Useful blog post (2022, last updated 2024) by Iris Eekhout showing how to update the predictor matrix and setup passive imputation using {mice} so that:
Items are imputed using (a) other items within a questionnaire and (b) other questionnaires’ total scores.
A total score is passively imputed on each run which becomes part of the MI process.
Theory-based evaluation – a possible Venn, with a long and often-forgotten history.
Example readings
Cook, T. D. (2000). The false choice between theory-based evaluation and experimentation. In A. Petrosino, P. J. Rogers, T. A. Huebner, & T. A. Hacsi (Eds.), New directions in evaluation: Program Theory in Evaluation: Challenges and Opportunities (pp. 27–34). Jossey-Bass.
Fitz-Gibbon, C. T., & Morris, L. L. (1975). Theory-based evaluation. Evaluation Comment, 5(1), 1–4. Reprinted in Fitz-Gibbon, C. T., & Morris, L. L. (1996). Theory-based evaluation. Evaluation Practice, 17(2), 177–184.
There’s nothing in theories of experiments requiring that researchers use a ridiculous control group. An example of such a ridiculous (and unethical) control would include randomising people who are living in abject poverty either to a regular sufficient social security payment or leaving them in poverty. Hmmm, what group will have a better outcome…?
The first example Rubin gave in his classic “Estimating causal effects of treatments in randomized and nonrandomized studies” (Rubin, 1974, p. 689) had the following two groups:
“… we will restrict discussion to the very simple study consisting of 2N units (e.g., subjects), half having been exposed to an experimental (E) treatment (e.g., a compensatory reading program) and the other half having been exposed to a control (C) treatment (e.g., a regular reading program).”
Lind’s (1753) study of scurvy treatments compared six treatments, including cider, vinegar, and sea water, as well as the oranges and lemons. Potentially unclear what the theoretical rationale was for all of those, so not ideal I’ll admit.
It’s pretty common now to use “business as usual”, “treatment as usual”, “teaching as usual”, etc., controls and to avoid waitlist controls. But this is not a new idea.
Additionally, Rubin didn’t use Y(1) and Y(0) for the two potential outcomes, but Y(E) and Y(C). It’s a very subtle difference; however, I wonder if ditching the zero helps people’s understanding. My preference would be something even closer to the names of the actual programs, e.g., if we are evaluating whether the Acme Compensatory Reading Programme is better than regular reading, Y(Acme) and Y(Regular) to emphasise the contrast. (Also now we would use “participants” rather than “subjects”.)
References
Rubin, D. B. (1974). Estimating causal effects of treatments in randomized and nonrandomized studies. Journal of Educational Psychology, 66(5), 688–701.
Lind, J. (1753). A treatise of the scurvy. In three parts. Containing an inquiry into the nature, causes and cure, of that disease. Together with a critical and chronological view of what has been published on the subject. Edinburgh: Printed by Sands, Murray and Cochran for A. Kincaid and A. Donaldson.
Always a fan of a counterfactual, I thought I’d give this thought experiment a try: If LLMs were around when I was an academic, how would I have advised students to use them? LLMs weren’t in widespread use about a hundred (four) years ago when I was teaching, so I shall begin with three similar activities and see if I can guess how I would have responded to LLMs.
Issues before LLMs
Copy-paste verbatim from sources
The easiest to spot. I’d often see this before running Turnitin. The usual clues were sections of dodgy, poorly argued and poorly referenced prose (not copy-pasted) and the occasional paragraph of tightly argued, edited, and well-cited prose (maybe copy-pasted?). Sometimes a change in font would give it away. But my “plagiarism checker” was often just Googling the obvious text.
Some students would copy from something on my reading list. I read things on my reading list before putting them there (gawd give me patience). I can’t think of any example where Turnitin revealed that a student was plagiarising. It sometimes helped me find additional examples of copy-paste in an essay that had already elevated my eyebrows.
My advice here would have involved going back to basics on writing essays.
Over-reliance on Wikipedia
Wikipedia is a fantastic resource (and I’m a Wikipedian), but it is often riddled with errors and omissions because it’s written by volunteers like you and me hacking sentences here and there, fixing issues when we happen upon them, generally with little time to do so.
The problem was that some students treated Wikipedia pages as if they were journal articles and cited them. I attempted to fix that problem by doing a live edit in class so students saw how Wikipedia works. The problems with relying on it are then obvious.
I suggested using Wikipedia to get unstuck when doing a literature search, e.g., by looking for terminology ideas to search for, or following a reference cited in an entry and things it cites and are cited by it. Wikipedia can be used to plug into the literature.
Copy-paste from sources and editing
You’re writing an essay on a topic you don’t really understand. So, you grab a collection of good references, copy and paste key paragraphs directly into your essay draft, and move the words around until you think it’s not plagiarism any more.
I’d usually spot this form of plagiarism because students sitting at 3am wired on caffeine and sugar would lose track of which bits they had edited and which bits were pasted from the source.
The alternative approach I offered was this (note: for narrative essays, not systematic reviews!):
Use a reference manager like Zotero to keep track of your sources.
Read a bunch of things, highlighting the PDFs and adding quick notes in the margins as you go.
Let the ideas wash around in your head for a bit.
Write notes (in a separate doc) on key points that stick, and revisit the papers to fill in details. The aforementioned highlights will help you get back to relevant sections.
The trick is to find the right distance between the verbatim text and the idea it expresses, to find themes across multiple papers rather than relying too much on one. Some specific details should obviously come verbatim from the paper, e.g., don’t let an effect size emerge from your mind.
What does any of this mean for LLMs
Back to the counterfactual. I suspect I’d probably have done something like the following:
Introduce a topic and ask students to do the readings.
Get an LLM or two to offer a summary of the topic, with references.
Discuss any gaps or inaccuracies or weird references.
I think my advice would have been similar to that for Wikipedia: you can use LLMs to get unstuck, to find a way into the literature. But then it is back to research as usual. I’m not sure I’d have any magical way to check if LLMs were used (I see there are checkers and they have problems). I’m curious to know if academics spot the use of LLMs because things aren’t cited properly: pretty obvious if you’re teaching a topic you know well, and highlights the importance of ensuring lecturers are asked to teach a topic that’s close to their research.
The other common use of LLMs, as a fancy grammar checker, doesn’t feel too terrible. Here I’d probably show a few examples live in class and ask students to break into small groups and discuss whether the resulting rewrite was better than the original. Again, LLMs can be helpful for getting unstuck. You have an idea for a sentence and can’t quite make it work. Ask Copilot for a few alternatives. They might all be rubbish but the process can help.
For example, I don’t like the following sentences that I tapped out above (but left as-is):
“I suggested using Wikipedia to get unstuck when doing a literature search, e.g., by looking for terminology ideas to search for, or following a reference cited in an entry and things it cites and are cited by it. Wikipedia can be used to plug into the literature.”
Copilot gave me:
“I recommended using Wikipedia as a resource to overcome obstacles during a literature search. This can include finding new terminology to search for, following references cited in an entry, and exploring the sources those references cite or that cite them. Wikipedia serves as a valuable tool to connect with the broader literature.”
Maybe this is better, but to me it feels a bit bland. I could have edited back to:
“I suggested using Wikipedia to get unstuck when doing a literature search. This can include finding new terminology to search for, looking up references cited in an entry, and exploring the sources those references cite or that cite them. Wikipedia can be used to find relevant literature.”
Here ends the counterfactual. I wonder how close it is to what I actually would have done…
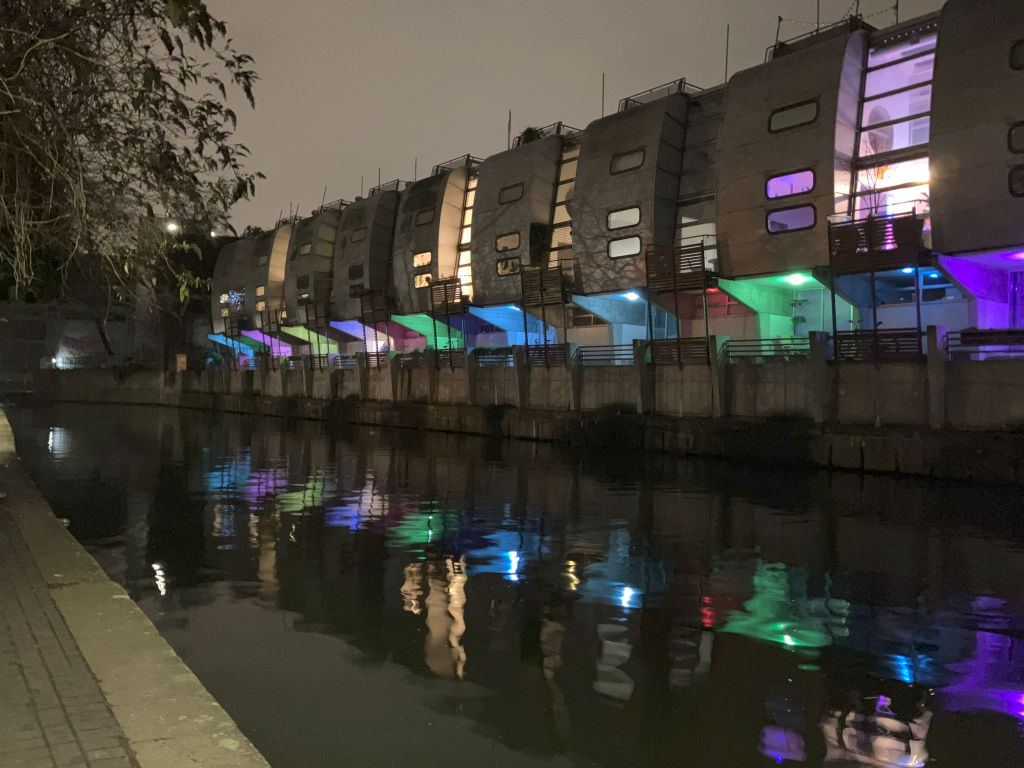
“In this commission for Sainsbury’s Grimshaw negotiated that residences should take the form of individual houses rather than a block of flats and the project includes 10 three-bedroom houses, a one-bedroom maisonette and a studio flat.”
“Consider a carefully controlled nonrandomized study – a study in which there are no obviously important prior variables that systematically differ in the E trials and the C trials. In such a study, there is a real sense in which a claim of ‘subjective randomization’ can be made. For example, if the study was composed of carefully matched pairs of trials, there might be a very defensible belief that within each matched pair each unit was equally likely to receive E as C in the sense that if you were shown the units without being told which received E, only half the time would you correctly guess which received E.”
Interesting thematic analysis (Cooper et al., 2015) of what helped and hindered in school-based humanistic therapy, as part of the large ETHOS RCT. The approach the researchers took started with open questions and coding inductively, then concluded with closed questions and deductive coding based on what the theory suggested might help or not. All the usual helpful things were there, like:
“[The therapist] wasn’t, like, doing something else. She was sat there all the time just like listening to me.”
“They just talked to me like I was a human being not like, ‘Oh, you know, what teenagers are like…'”
“It was like they were taking in what I was actually saying and then the questions afterwards were based upon that.”
I was struck by the number of young people who mentioned the therapist providing advice, given that the humanistic approach is supposed to be non-directive (there is some discussion of this). Sometimes this advice was welcome and young people who didn’t receive any advice indicated that they didn’t see the point of therapy without it.
“I used to have an argument with this girl…and the therapist said to just leave it because she’s just going to– she wants attention and she wants a reaction out of me. She [the therapist] was just like, “Leave it. She can say whatever she wants and then she’ll stop it herself,” and now that girl doesn’t even say anything to me because I don’t even say anything to her.”
Advice/guidance wasn’t always experienced as helpful; the examples given seem to be all “technique”:
“[The therapist] would do breathing exercises and imagine things, and I didn’t like that. I said, “I didn’t like that,” and [the therapist] was like, “Well, let’s just try.” “I don’t want to do it.” “Well, let’s just try.” [The therapist] was kind of persistent on something that I didn’t want to do.”
There’s also a collection of things some therapists did which were seen as particularly unhelpful, e.g.,
“She didn’t have a lot to say. She would just sit there and stare at me for sometimes three minutes at a time. Literally it was three minutes. She’d just sit there, and I’d be looking around the room, and every time I looked back at her, she’s just looking at me. She wouldn’t say anything.”
(Reminds me of Levitt’s 2001 thematic analysis of the twenty or so different kinds of silence!)
Wonder if anyone has tried to crowdsource these helpful/hindering ideas at scale.
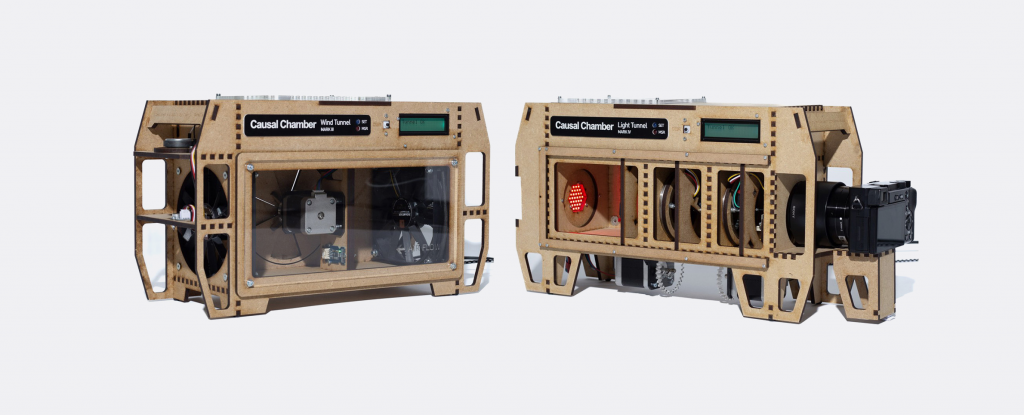
Fun research providing an alternative to computer-based data simulation for developing and testing machine learning algorithms: Gamella, Peters, and Bühlmann (2025) built two physical devices (“causal chambers”) consisting of a light tunnel and wind tunnel. These devices were designed so that the underlying physical systems are well understood, which means that the true causal models are known. The systems are automatically controlled, allowing large quantities of data to be produced. The authors provided case studies for out-of-distribution generalization, change point detection, independent component analysis (ICA) and symbolic regression.
The Five Safes could be a good way to help think about making data available to “turbocharge” AI [1, 2]. Maybe they already are – but the comms needs to accelerate if so.
Safe projects: Is the proposed use of the data (e.g., ethically) appropriate?
Safe people: Can the analysts be trusted to use it in an appropriate manner? Accredited Researcher registers that many of know and love might help.
Safe data: Is there a disclosure risk in the data itself?
Safe settings: Does the access facility limit unauthorised use? Interesting for cloud-based compute.
Safe outputs: Are the statistical results non-disclosive? This will be particularly challenging for models with millions of parameters.
These are five dimensions and they all need to be considered together to determine whether an approach to making data available is safe. For example if it’s impossible to entirely anonymise data, then the other dimensions need to be beefed up.
[1] Prime Minister sets out blueprint to turbocharge AI. Department for Science, Innovation and Technology, Prime Minister’s Office, 10 Downing Street, The Rt Hon Peter Kyle MP, The Rt Hon Sir Keir Starmer KCB KC MP and The Rt Hon Rachel Reeves MP (13 Jan 2025)
“Let’s pause for a moment and ask a very basic and very important question: what is theory? We start by answering in the negative: the production of theory is not necessarily a scholastic exercise; the site of production of theory is not necessarily the ivory towers of academia; the producers of theory are not necessarily academically trained personnel in possession of qualifications that bestow on them the status of ‘officially approved theorists’.
“Positively, we would argue that the building blocks of the production of theory are the efforts of ordinary people to make sense of their social experience; the sites of production of theory are, then, everywhere such activity may take place; the producers of theory are – potentially – everyone who engages in reflection on their experiences so as to develop new and improved practices to problematic aspects of that experience.”