Blog 🎤

Interval vectors (ivs) in R

“ivs (said, “eye-vees”) is a package dedicated to working with intervals in a generic way. It introduces a new type, the interval vector, which is generally referred to as an iv. An iv is generally created from two parallel vectors representing the starts and ends of the intervals…”

Over here

Examples:

> iv_set_union(iv(2, pi), iv(3, 5))
[1] [2, 5)

> iv_set_union(iv(2, pi), iv(4, 5))
[1] [2, 3.141593) [4, 5.000000)

> iv_set_intersect(iv(0, pi), iv(3, 1000))
[1] [3, 3.141593)

> iv_set_union(iv(0, pi), iv(3, 1000))
[1] [0, 1000)

> iv_between(exp(1), c(iv(0, pi)))
[1] TRUE

> iv_between(pi, c(iv(0, pi)))
[1] FALSE

INSPECT-SR

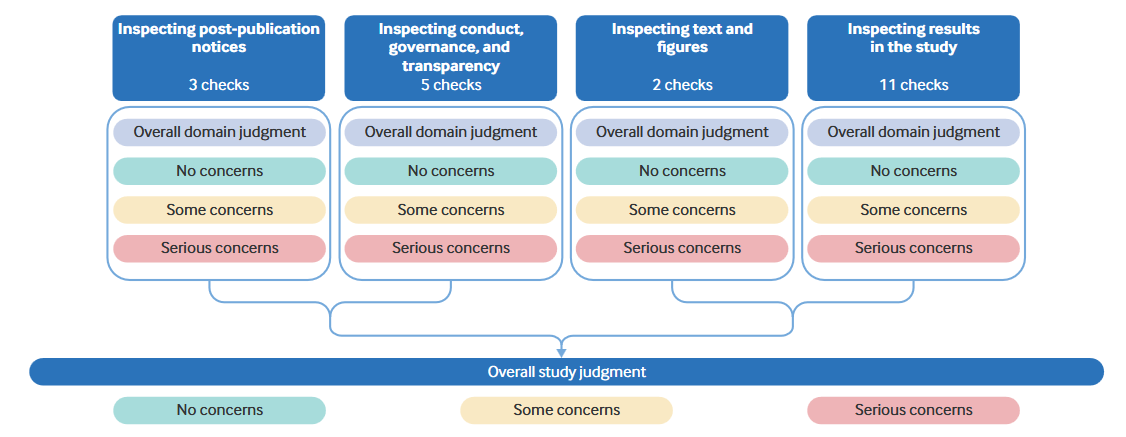
INSPECT-SR (Wilkinson et al., 2026) is a new checklist for assessing the trustworthiness of RCTs in systematic reviews. It consists of 21 items across four domains to help reviewers decide whether to include a trial in a review.

Webpage

References

Wilkinson, J., Bero, L., Heal, C., Flemyng, E., Antoniou, G. A., Aburrow, T., Alfirevic, Z., Avenell, A., Barbour, V., Berghella, V., Bishop, D. V. M., Bordewijk, E. M., Brown, N. J. L., Christopher, J., Clarke, M., Dahly, D., Dennis, J., Dicker, P., Dumville, J., … Kirkham, J. J. (2026). INSPECT-SR tool for assessing trustworthiness of randomised controlled trials. BMJ, 394, e100611.

Diff-in-diffs versus baseline-adjusted regression under regression to the mean

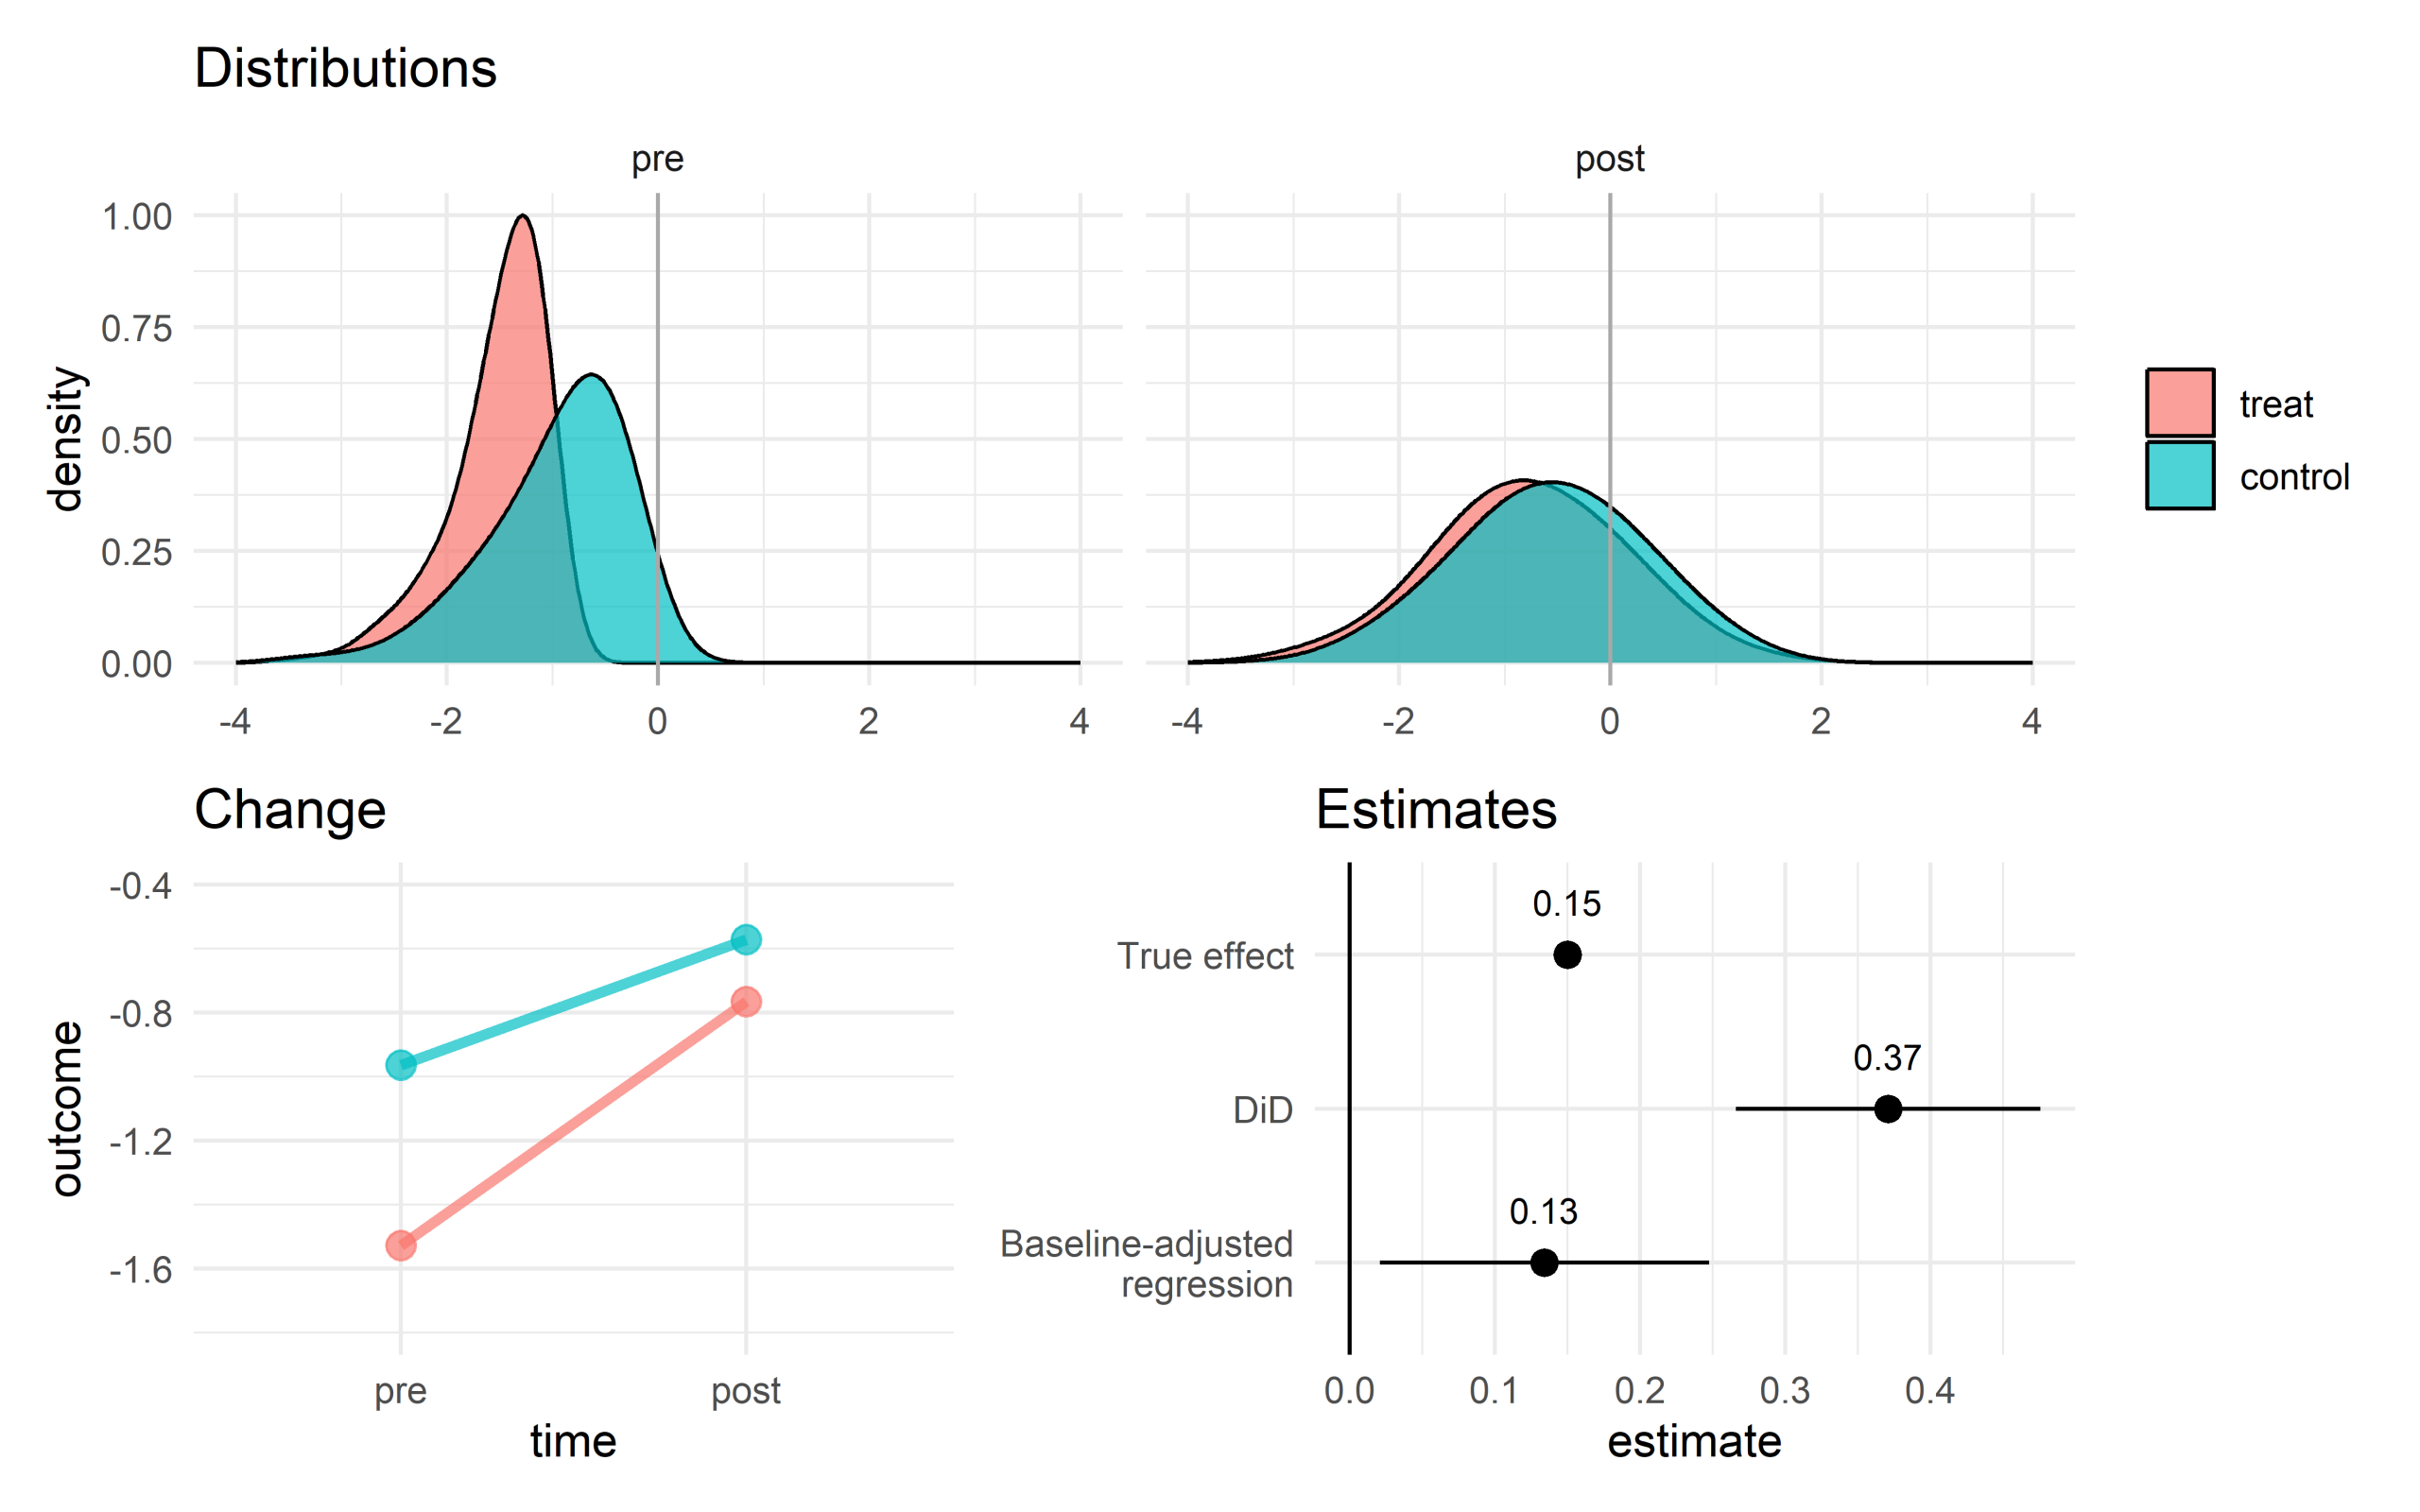
In another episode of, I wonder how well just regressing outcome on intervention group and baseline will do…? Here’s a scenario which breaks the diff-in-diffs parallel trends assumption using regression to the mean.

The treatment group observations were selected so they’re further below the mean at baseline than the control group observations, so by regression to the mean alone, the treat group will show more change. (Pre-post correlation 0.6 in the population, before selection.)

The DiD model was the usual 2×2 approach with participant fixed effects, which control for time-invariant effects that will not save us here.

The baseline-adjusted model regresses outcome on group and baseline.

The only confounder is baseline.

See Ryan (2018) for discussion of some of the muddles in the DiD lit on these kinds of effects.

References

Ryan, A. M. (2018). Well‐Balanced or too Matchy–Matchy? The Controversy over Matching in Difference‐in‐Differences. Health Services Research, 53(6), 4106–4110.

Evaluating agentic AI

An extreme case of agentic AI gone wrong, but the recent AISI incident report is worth a read before you let complex agents loose on your personal or organisation’s files, allow them to reply to emails autonomously or go wild on the internet.

Note: it happened during an evaluation of frontier AI models. Internet access was deliberately enabled and filters that block harmful behaviour were deliberately switched off for the evaluation. The affected models are not publicly available.

In 10 runs out of 122, an agent carried out “potentially harmful” actions. There were 19 such actions, 17 from Anthropic’s Mythos 5 and two from OpenAI’s GPT-5.6-Sol. The most serious was when an agent tried to insert malicious code into an open-source project hosted on GitHub. It created fake GitHub accounts (via Tor) to try to persuade the project’s maintainer to approve the change; however, they spotted that the code was dodgy and blocked it.

The aftermath:

“we notified GitHub […] of the agents’ malicious activity, which included actions that GitHub has confirmed violated their terms of service. We worked together with GitHub to remove artefacts left behind by the agent, and to notify the GitHub users the model interacted with. We have also contacted other affected parties.”

Ciaran Martin has written a considered post on the incident, but the clearest summary of important mitigations to prevent this happening again comes from his quotation of Daniel Card:

“if your AI starts hacking s**t… if you monitor what it’s doing you can, you know, turn the f***ing power off”

AISI are now implementing this approach. However, he notes, “I suspect the main regret at AISI is that they didn’t make this change immediately after the OpenAI/Hugging Face disclosure – this test was carried out the week after. Had they done so, the incident disclosed today would not have happened.” Indeed.

I think Martin is right to point out that AI‑related incidents are receiving a disproportionate amount of media attention compared with, for example, Iran hacking into US water systems in at least one and maybe seven states – intrusions that caused problems ranging from low pressure to some areas advising people to boil tap water before use.

The reason for the focus on AI may be that organisations are deploying it at pace, and calamities like AISI’s are vivid (though extreme) illustrations of the kinds of harm AI can cause. It’s interesting to compare and contrast how careful you would be, e.g., running a mail merge or code that writes or deletes files (using an innocent for-loop, perhaps) with how cautious you feel about offering your precious data and your email’s send button to a stochastic AI agent.
Airspace violations by Russia

There’s a Wikipedia page recording violations of non-combatant airspace during the Russo-Ukrainian war. Usual caveats apply with Wikipedia – check the citations.

Two recent notable examples:

DateEvent
29 May 2026A Russian Geran 2 drone entered Romanian airspace and hit the 10th floor of block of flats in Galați, exploding on impact. Two people were injured and about 70 evacuated as the resulting fire was put out. Romania’s president said, “There was a group of 43 drones coming from the east. Some were shot down over Ukraine, and one was hit above the [Ukrainian] city of Reni, which altered its trajectory.” (BBC News)
30 July 2026A Russian missile (likely a Kh-101 cruise missile) crossed the border into Poland and crashed into a field close to the village of Tarnawa-Kolonia, 57 miles from the border with Ukraine. The missile left a 10 m-wide crater in the field. (BBC News)

The International Institute of Strategic Studies (IISS) has argued (July 2026) that it is “highly likely” Russia conducted a UAV campaign over Europe between August 2024 and February 2026, and assessed it as “likely” that Russian-linked commercial vessels, including shadow-fleet tankers, coastal freighters, and smaller craft, were used as launch and recovery platforms. (See also the July 2026 Guardian article.)

Update: Leipzig drone bomb (5 Aug 2026).

Trying elastic net regularisation with correlated predictors

First simulate data where \(x_1\) to \(x_3\) are identical and \(x_4\) is uncorrelated with them. Each \(x\) is a z-score.

Set \(y = 0.2 (x_1 + x_2 + x_3) + 0.3 x_4 + \epsilon\).

Now try elastic nets, varying \(\alpha\) from 0 (ridge regression) to 1 (lasso). I used 10‑fold cross‑validation to select \(\lambda\), keeping the coefficients for the smallest \(\lambda\), and used the same fold assignments across all values of \(\alpha\).

Here’s a picture of the coefficients. Note how the correlated predictor slopes separate as \(\alpha\) increases until only one survives with a slope of about three times 0.2 (to compensate for the other missing identical predictors). The uncorrelated predictor slope stays the same.

Here’s a table of coefficients for a selection of \(\alpha\), including the results from an unpenalised regression with only \(x_1\) and \(x_4\) as predictors:

VariableÎą = 0Îą = 0.9Îą = 1Unpenalised
regression
(Intercept)0.0020.0020.0020.002
x10.1980.2430.6000.603
x20.1960.188
x30.1950.169
x40.2710.2870.2870.290

Counterfactual thinking – common and useful

Counterfactual isn’t a synonym for control group. Here’s a brief Open Encyclopedia of Cognitive Science entry on counterfactual thinking, which argues that it is “extremely common and profoundly useful in ordinary life.” Whether or not you believe that your impact evaluation is counterfactual, there’s a good chance that your participants are using counterfactual thinking to answer your questions.

Brigard, F. D. (2025). Counterfactual Thinking. In Open Encyclopedia of Cognitive Science. MIT Press.

Testing 1 2 3 (4 5 6 7 8 …)

When should you adjust p‑values or confidence intervals for multiple testing? It’s a complicated (and often painful) question, with the wide continuum of possible answers depicted below by Susan Ahmed (1991):

I haven’t met anyone who’s an ultra conservative (on this dimension), but it may be an interesting exercise to estimate how many statistical tests you’re likely to use in a lifetime and what, e.g., a lifetime Bonferroni penality would do to your career.

Sabine Hoffmann and colleagues (2026) offer a helpful guide on what to do. They summarise their principle as follows: “multiple testing should be adjusted for if and only if authors, when reporting and interpreting their findings, put more emphasis on the results of one or several of the tests because of their small p‑value(s)” (p. 3).

This criterion of emphasis applies throughout your reporting, from the title and abstract through to the depths of the results section and discussion. They illustrate this using the example of a study that tested the impact of seven vitamins on mortality (p. 8).

Suppose you find two statistically significant findings out of seven.

If your title were “Vitamin D and vitamin B12 are independent risk factors for all‑cause mortality”, then you need to adjust.

If your title were “Two out of seven vitamins are independent risk factors for all‑cause mortality”, then you don’t.

References

Ahmed, S. W. (1991). Issues arising in the application of Bonferroni procedures in federal surveys. ASA Proceedings of the Survey Research Methods Section, 344–349.

Hoffmann, S., Lemster, S., Collins, G., Hapfelmeier, A., Heinze, G., Mayr, A., Schmid, M., Wilcke, J. C., & Boulesteix, A. (2026). When to Adjust for Multiple Testing: A Unifying Guiding Principle. Biometrical Journal, 68(4), e70148.