If you need evaluation findings sooner than the time it takes (1) to recruit enough participants for adequate statistical power, plus (2) the time for the final participant to complete the programme and have their outcome measured, plus (3) analysis and reporting time, then you need to conduct a literature review instead. Though you may want to run an evaluation too, so there is relevant literature to review in future.
The paragraph above summarises many talks on policy timelines, past and future. See also Bending evaluation timelines to meet policy deadlines.
Tag: policy evaluation
Theory of change
The “change” in “theory of change” is often interpreted as meaning change over time, which can be misleading. If a programme is designed to prevent an outcome from occurring (for example, a worsening of mental health), then there may be no pre-post change at all. Alternatively, any observed pre-post change may be driven by regression to the mean or by factors other than the programme under evaluation.
In a counterfactual impact evaluation, the “change” of interest is the expected or desired causal effect (or “treatment” effect). This is the difference between two potential outcomes: the outcome that would occur under exposure to the programme and the outcome that would occur under the control or comparison condition. Rather than describing outcomes in isolation, the theory should define the contrast between these two potential outcomes, for example whether the programme outcome is expected to be higher or lower than the control outcome.
Taking a logic model list, this would mean replacing the usual outcomes and impacts with causal effects on various time scales. It needs a name though. Some ideas:
- Theory of causal effect (ToCE/TCE)
- Theory of programme effect (ToPE/TPE)
- Theory of causal contrast (ToCC/TCC)
- Theory of difference (ToD/TDD)
- Theory of expected difference (ToED/TED)
Alternatively, maybe it’s time to return to “programme theory” or just “theory”.
INSPECT-SR
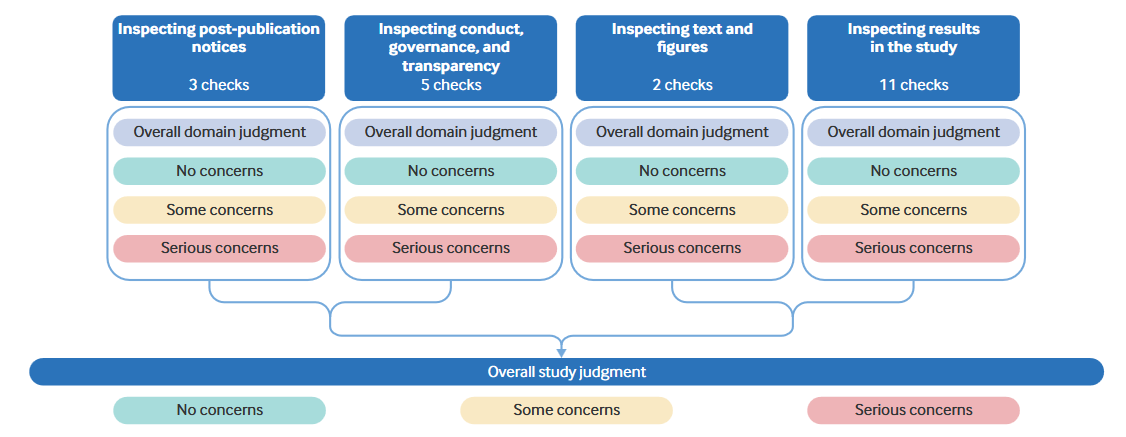
INSPECT-SR (Wilkinson et al., 2026) is a new checklist for assessing the trustworthiness of RCTs in systematic reviews. It consists of 21 items across four domains to help reviewers decide whether to include a trial in a review.
References
Wilkinson, J., Bero, L., Heal, C., Flemyng, E., Antoniou, G. A., Aburrow, T., Alfirevic, Z., Avenell, A., Barbour, V., Berghella, V., Bishop, D. V. M., Bordewijk, E. M., Brown, N. J. L., Christopher, J., Clarke, M., Dahly, D., Dennis, J., Dicker, P., Dumville, J., … Kirkham, J. J. (2026). INSPECT-SR tool for assessing trustworthiness of randomised controlled trials. BMJ, 394, e100611.
Counterfactual without a comparison group
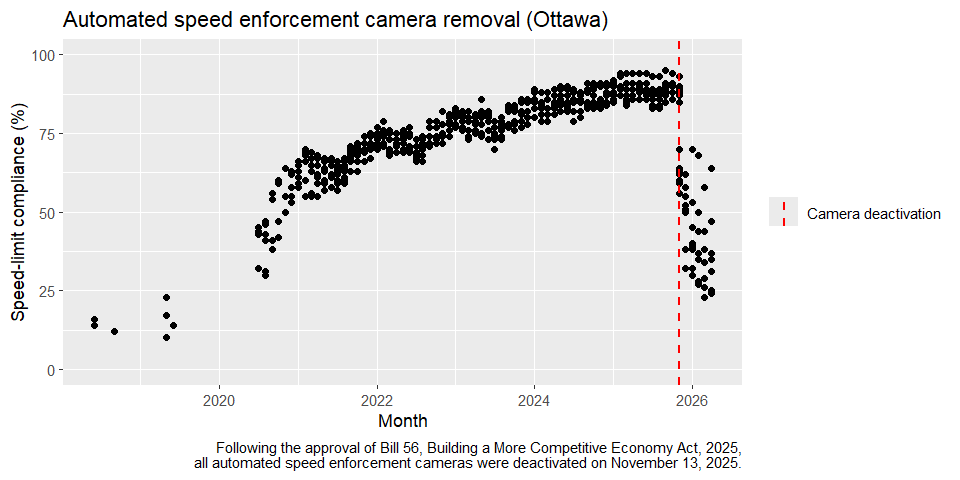
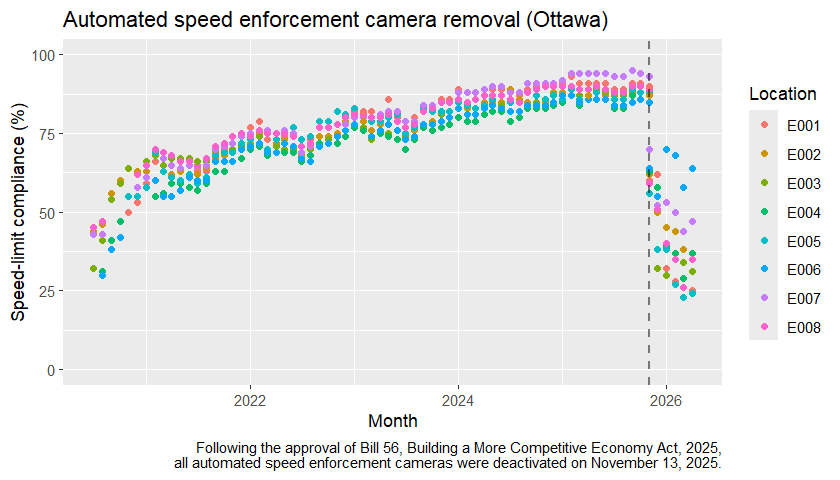
“Following the approval of Bill 56, Building a More Competitive Economy Act, 2025, all automated speed enforcement cameras were deactivated on November 13, 2025. The city has since been collecting and analyzing speed data at the original eight pilot locations to evaluate the impact of the camera removals. Monthly updates are provided for each site, including average speed, 85th percentile speed, speed-limit compliance rates, and the proportion of high-end speeders. This data is presented alongside baseline conditions prior to ASE camera installation and results observed during the enforcement period.”
Data here (hat tip @sjamieit.bsky.social). Here’s a pic, drawn using ggplot in R.
Value free governments
“[… I]t is accepted that the social scientists’ contribution cannot be value free but, surprisingly, much less attention has been given to the much more obvious fact that governments are not value free either. The fact that they are not means that the problem facing the social scientist in government is not so much that his own value system colours his research and recommendations, but that these values may be out of tune with those of the government he is advising.” (Sharpe, 1976, pp. 75–76)
References
Sharpe, L. J. (1976). Government as Clients for Social Science Research. Zeitschrift Für Soziologie, 5(1), 70–79.
Useful science (and evaluation?) for policy
“A policy problem is not usually the same as a scientific problem, and may have several scientific problems incorporated within it.”
“Scientists can be advocates, or they can provide the best possible balanced assessment of the evidence but they cannot do both simultaneously. It has to be clear to policymakers which horse they are riding. Papers seen as advocacy are likely to be discounted.”
“Since the policy process tends to be very fast, papers must be timely. An 80% right paper before a policy decision is made it is worth ten 95% right papers afterwards, provided the methodological limitations imposed by doing it fast are made clear.”
“Sensible policymakers prefer a paper they understand, including its flaws, to one they do not, however sophisticated and apparently precise it looks. It is possible to be simple whilst being rigorous.”
“Policymaking is a professional skill; most scientists have no experience of it and it shows. […] Worse, trying to work up to a policy position can unconsciously bias scientists towards trying to get a neat policy narrative from a complex picture, or downplay inconvenient facts.”
“Some scientists seem to assume a two-stage process where the individual research is conducted, and then policies made on the basis of that. The reality should be a three-stage process: that original research is conducted, then research from multiple instances and disciplines is synthesised, and then policies made on the basis of all the available synthesized evidence.”
References
Whitty, C. J. M. (2015). What makes an academic paper useful for health policy? BMC Medicine, 13(1), 301, s12916-015-0544–0548. https://doi.org/10.1186/s12916-015-0544-8
The kind of researcher needed for policy research and evaluation (Donnison, 1972)
David Donnison’s (1972, p. 532) view on the qualities required for someone to be an effective policy researcher or evaluator:
“The research workers to look for should of course be the most creative and intelligent we can find. But their motivation is equally important and harder to assess. They must have a policy-oriented cast of mind, or be likely to acquire that in time. They must enjoy thinking in a sustained, rigorous and independent way about the problems of government – which means they take seriously the version of a problem perceived by the government of the moment, but do not confine their own perception of the issues to that version alone. They must want to make the world a better place for people already living in it: the needs of future generations should not be wholly neglected, but neither should they be the main concern. And they must enjoy studying how that could be achieved with the resources potentially available for the task – which calls for a capacity to envisage the alternative uses to which such resources might be put. […]”
“Responsible scholars recognise that if they are to present conclusions which might ultimately affect many of their fellow-citizens they must be more, not less, careful about the quality of their evidence and the logic of their argument than they would be if they intended only to communicate with their academic colleagues. […] They should not be tempted to become politicians – a reputable but entirely different role. They should remain firmly rooted in the academic world – whether they work in universities or not – where they can keep in touch with their colleagues and students and draw on their help.”
Donnison, D. (1972). Research for policy. Minerva, 10(4), 519–536.
P.S. I’m not convinced by the comment on future generations – perinatal programmes and net zero policies are example areas where evaluators should and do consider impacts on future generations.
What should the is-ought thesis state?
Hume’s is-ought thesis states that we cannot infer a normative statement about what we should do from a descriptive statement about what is the case. This post spells out some of the detail about what the thesis means, which should be of interest to policy evaluators since we’re in the business of producing evidence and offering advice on policy that’s consistent with that evidence.
Let’s start with Prior’s (1960) puzzle (mildly edited): what kind of statement is “Either it’s raining or cricket should be banned”? It combines a descriptive statement (“it’s raining”) with a normative one (“cricket should be banned”), but is the disjunction of the two descriptive or normative?
Suppose Prior’s puzzle is a descriptive statement. Then by adding it to the premise “it’s not raining”, we can derive the purely normative conclusion that “cricket should be banned”. Since the disjunction is true, but one of its disjuncts is false, then the other disjunct must be true. We have just drawn an is-ought inference.
In symbols,
\(\displaystyle \neg R, R \lor \mathsf{O} B\ \models\ \mathsf{O} B\),
where \(R\) denotes “it’s raining”, \(\mathsf{O} B\) denotes that we ought to ban cricket (the \(\mathsf{O}\) is the “ought” from deontic logic), \(\lor\) is disjunction (or), \(\neg\) is negation, and \(\models\) is logical consequence.
This is maybe easier to see by rewriting the disjunction as a conditional, “If it’s not raining, then cricket should be banned” (since \(\neg \phi \lor \psi = \phi \rightarrow \psi\)):
\(\displaystyle \neg R, \neg R \rightarrow \mathsf{O} B\ \models\ \mathsf{O} B\),
where \(\rightarrow\) is the material conditional. The conclusion is then drawn by modus ponens. This pattern is interesting for evaluation, since it mirrors the logic:
- The programme works*.
- If the programme works*, we should roll it out nationally.
- Therefore, we should roll it out nationally.
Where works* includes a range of statements about impact and process evaluation evidence, whether that evidence can be generalised to a broader population, whether the programme avoids causing harm, its cost‑effectiveness, and other considerations.
In symbols,
\(\displaystyle W^*, W^* \rightarrow \mathsf{O} R\ \models\ \mathsf{O} R\),
where \(W^*\) denotes the programme works* and \(R\) denotes that we should roll it out.
Suppose instead that Prior’s puzzle is a normative statement. Starting from the purely descriptive premise “it’s raining”, we can infer “Either it’s raining or cricket should be banned” by disjunction introduction. Again, we have drawn an is-ought inference.
In symbols,
\(\displaystyle R\ \models\ R \lor \mathsf{O} B\).
Rewriting using implication,
\(\displaystyle R\ \models\ \neg R \rightarrow \mathsf{O} B\),
the conclusion is one of the “paradoxes” of the material conditional: true under classical logic because the antecedent is false, but people tend to judge the conditional to be neither true nor false but irrelevant (Johnson-Laird & Tagart, 1969).
The solution is, “Either it’s raining or cricket should be banned” is neither descriptive nor normative: it’s mixed. The same applies to “If the programme works*, we should roll it out nationally”. Three refinements of the is-ought thesis are provided in a logic-heavy book by Schurz (1997), which has been on my reading stack for years. A more digestible summary is provided by Schurz (2014, pp. 2–3):
(H1) No non-logically true purely normative conclusion can be derived from a consistent set of purely descriptive premises.
(H2) Every mixed conclusion [i.e., combining descriptive and normative statements] which follows logically from a set of purely descriptive premises is normatively irrelevant in the sense that all of its normative subformulas are replaceable by other arbitrary subformulas, while preserving the validity of the inference [“salva validitate of the inference” in Schurz’s original].
(H3) No non-tautologous descriptive statement can be inferred from a consistent set of purely normative premises.
H1 is the thesis that applies most to evaluation: to make an evaluative judgement, you need mixed premises that blend normative and descriptive statements. H2 deals with weird uses of logic. I’ve used the principle of irrelevance it contains to help understand how people reason about sentences like “If Alex posted the letter, then he posted the letter or set fire to the letter”, which are true in classical logic but which people often judge to be false (Fugard et al., 2011). There’s a blog post about it yonder. H3 says that knowing or believing what should be true doesn’t tell you what is factually true.
There is, however, a well‑known problem with using the material conditional in combination with oughts (Chisholm, 1963), e.g., \(W^* \rightarrow \mathsf{O} R\) used above. Consider the following sentences and formalisations:
- It ought to be that Jones goes to assist his neighbours: \(\mathsf{O} g\).
- It ought to be that if Jones goes, then he tells them he is coming: \(\mathsf{O} (g \rightarrow t)\).
- If Jones doesn’t go, then he ought not tell them he is coming. \(\neg g \rightarrow \mathsf{O} \neg t\).
- Jones doesn’t go: \(\neg g\).
The English‑language statements feel consistent with each other. They are also independent in the sense that no one sentence follows from any of the others. A formalisation should preserve both features.
There are three paths through, using what has come to be known as standard deontic logic (SDL). McNamara and Van De Putte (2025, Section 2.1) provides an introduction to SDL. Section 4.1 provides the illustration of Chisholm’s (1963) problem, which I’ve just spelt out a little. Here’s a summary of the paths:
| Path A | Path B | Path C |
|---|---|---|
| (1′) \(\mathsf{O}g\) (2′) \(\mathsf{O}(g \rightarrow t)\) (3′) \(\neg g \rightarrow \mathsf{O}\neg t\) (4′) \(\neg g\) | (1′) \(\mathsf{O}g\) (2′) \(\mathsf{O}(g \rightarrow t)\) (3″) \(\mathsf{O}(\neg g \rightarrow \neg t)\) (4′) \(\neg g\) | (1′) \(\mathsf{O}g\) (2″) \(g \rightarrow \mathsf{O}t\) (3′) \(\neg g \rightarrow \mathsf{O}\neg t\) (4′) \(\neg g\) |
| From (1′), (2′), \(\mathsf{O}t\). From (3′), (4′), \(\mathsf{O}\neg t\). Consistency is lost. | (1′) implies (3″). Independence is lost. | (4′) implies (2″). Independence is lost. |
Following Path A, we deduce that Jones ought to tell them he is coming and ought not tell them he is coming, which is suspect. This uses the following SDL rule:
\(\mathsf{O}(\varphi \rightarrow \psi) \rightarrow (\mathsf{O}\varphi \rightarrow \mathsf{O}\psi)\text{,} \tag{OB-K}\)
which gives us \(\mathsf{O}g \rightarrow \mathsf{O} t\) (from 2′). This (alongside 1′) gives us \(\mathsf{O}t\) by modus ponens. We can also get \(\mathsf{O}\neg t\) using modus ponens (3′ and 4′). It also contradicts one of the axioms of SDL: if you should do something, then you shouldn’t also do the negation of that something:
\(\mathsf{O} \phi \rightarrow \neg \mathsf{O}\neg \phi \tag{NC}\)
Paths B and C attempt to use the same expression for the conditional oughts in sentences 2 and 3. Path B uses
\(\mathsf{O}(\phi \rightarrow \psi)\).
Path C uses
\(\phi \rightarrow \mathsf{O}\psi\),
which we encountered above when exploring Prior’s (1960) puzzle.
The problem with both attempts to save SDL is that the sentences become dependent, whereas in the original informal English they aren’t. For Path B, \(\mathsf{O}(\neg g \rightarrow \neg t)\) is vacuously true (when rewritten using OB-K) because \(\mathsf{O}g\) is true – a paradox of the material conditional again. Similarly for Path C, \(g \rightarrow \mathsf{O}t\) is vacuously true because \(\neg g\) is.
So however we choose to formalise the sentence “if you should do A, then you should do B” or “if A, then you should do B”, it is not something that can be captured within SDL – a conclusion reached in the late 1960s (Parent & Torre, 2018, p. 20). This conclusion is familiar from work in the psychology of reasoning, where the material conditional is replaced with systems that behave more like everyday inference.
One approach uses defeasible logics, which allow us to retract a conclusion when new information arrives and to treat some premises as having greater priority than others (e.g., Neves et al., 2002). Another approach uses probability logics, which model reasoning under uncertainty (e.g., Pfeifer & Kleiter, 2009). Probability logics typically rely on an underlying three‑valued semantics, in which a statement can be true, false, or neither. The third value is usually interpreted as something like “irrelevant” or “undetermined”.
A recent review of deontic logic (McNamara & Van De Putte, 2025) concludes that “there are a number of outstanding problems for deontic logic. Some see this as a serious defect; others see it merely as a serious challenge, even an attractive one.” I’ve been reading attempts to solve some of these problems, e.g., Horty (2012), which applies defeasible logic to deontic reasoning. See the follow-up.
References
Chisholm, R. M. (1963). Contrary-to-duty imperatives and deontic logic. Analysis, 24, 33–36.
Fugard, A., Pfeifer, N., & Mayerhofer, B. (2011). Probabilistic theories of reasoning need pragmatics too: modulating relevance in uncertain conditionals. Journal of Pragmatics, 43, 2034–2042.
Horty, J. F. (2012). Reasons as defaults. Oxford University Press.
Johnson-Laird, P., & Tagart, J. (1969). How implication is understood. The American Journal of Psychology, 82, 367–373.
McNamara, P., & Van De Putte, F. (2025). Deontic logic. In E. N. Zalta & U. Nodelman (Eds), The Stanford encyclopedia of philosophy (Winter 2025). Metaphysics Research Lab, Stanford University.
Neves, R. D. S., Bonnefon, J.-F., & Raufaste, E. (2002). An Empirical Test of Patterns for Nonmonotonic Inference. Annals of Mathematics and Artificial Intelligence, 34, 107–130.
Parent, X., & Torre, L. van der. (2018). Introduction to Deontic Logic and Normative Systems. College Publications.
Pfeifer, N., & Kleiter, G. D. (2009). Framing human inference by coherence based probability logic. Journal of Applied Logic, 7, 206–217.
Prior, A. N. (1960). The autonomy of ethics. Australasian Journal of Philosophy, 38(3), 199–206.
Schurz, G. (1997). The Is-Ought Problem: An Investigation in Philosophical Logic. Springer.
Schurz, G. (2014). Cognitive success: Instrumental justifications of normative systems of reasoning. Frontiers in Psychology, 5(625).
The value of deferring strong evaluative judgement
This post continues my ruminations on values and evaluative judgements, and considers whether the scarcity of explicit evaluative judgements in reports is really a bad thing. It’s thinking in progress.
The story so far… Evaluation is frequently defined as “the process of determining the merit or worth” of things (Scriven, 1994, p. 152). However, a review of 13 broad evaluation approaches identified only three that provided any guidance on how to make these judgements (Schröter et al., 2026), and this is reflected in practice. A gallon (95% CI 0.8 to 1.2) of ink has been spilled arguing that we need more explicit evaluative judgements.
The argument, roughly and vastly oversimplifying, goes like this: in light of the is-ought gap, evaluative judgements require values. We should make those values explicit and blend them with the (theory‑laden) facts that the evaluation yields to obtain an explicit (value‑laden) judgement. Rubrics are one way to record agreed values and, its proponents argue, help us to reach an evaluative conclusion (King et al., 2013).
Three (value‑laden) facts trouble me about calls for evaluators to provide more explicitly argued evaluative judgements.
Firstly, arguments are often enthymemes: they rely on premises that are left implicit. This is well studied in philosophy, linguistics, and the psychology of reasoning (my PhD was on the latter). It would be extremely difficult to communicate at all if we had to spell out every premise, and it turns out that we are often very good at filling in the gaps. Grice, among others, described a set of conversational conventions that we seem to follow and that help us do this. For instance, if someone says that “Jane ate some of the ice cream”, we typically conclude that she did not eat all of it, even though that conclusion does not follow from classical logic. If she had eaten all of it, then to comply with one of Grice’s principles we would say so.
People draw similar enthymematic inferences when moving from an is to an ought. To take an easy example, from premises like “If you pull the dog’s tail again, then he’ll bite you”, people conclude “You should not pull the dog’s tail”, apparently implicitly inferring a bridging premise that fills in the is-ought gap (Elqayam et al., 2015). A key driver of these inferences is that descriptive sentences are often value-laden, e.g., being bitten by a dog is judged to be bad. Findings from evaluations are usually value-laden too, concerning outcomes such as improved health or educational attainment. However, logicians and philosophers strive to make any is-ought gaps explicit in their analyses.
Secondly, systematic reviews are frequently required to assess evidence, and what you tend to find is that it takes time for patterns in findings to be identified. There is variation in study quality, particularly in the earliest evaluations of a programme. Over time, moderators of change are identified – if you’re lucky, and enough studies have been conducted in sufficiently many contexts. There is also the issue of publication bias, which can take a while to detect, and early optimism about effect sizes is often attenuated. All of this means it can be unwise to rely too heavily on a single evaluation. Yet, in practice, evaluators are not funded to conduct a systematic review once they have finished evaluating a programme in a single context.
Thirdly, there is obviously vast diversity in the values people hold. For example, a YouGov poll a few years back found that around half of Conservative and Leave voters thought the British Empire was something to be proud of, and that former colonies were better off for having been colonised. Roughly 40 percent of them said they would like Britain still to have an empire! Among Labour and Remain voters, only about 20 percent expressed pro‑empire views. Listen to callers on LBC Radio and you will hear equally varied views on, e.g., racism and immigration, and consequent policy suggestions.
Diversity of values applies across a wide range of policy areas that have a huge impact on people’s lives, and that many of us do or will work on. Consider, for example, contemporary debates on holding people in immigration removal centres; the activities of big tech companies; welfare benefit policy and conditionality; how transgender people are treated; or the experiences of people in mental health inpatient units.
Mabry (2010, p. 84) summarises the problem faced by evaluators co-creating rubrics:
“Those who promote attention to the values of stakeholders beyond those of program managers or funders […] often refer optimistically to the importance of building consensus. But the diversity of stakeholder interests may be irreconcilable, and evaluation’s capacity to clarify differences may cement dissensus. Moreover, […] every taxpayer, every citizen, every resident is a remote stakeholder, introducing a diversity of social values that could overwhelm an evaluation.”
Of course, the fact that it is often challenging to reach consensus on values does not mean that we shouldn’t try to do so. Alternatively, we may have to draw more than one evaluative judgement depending on whose values are added to the premises of the argument, or prioritise the values of service users. However, as Mabry’s argument suggests, we may often be stepping into territory that an evaluator’s judgement alone cannot settle.
Regardless of how explicit we are about value judgements, evaluation – like the rest of science – is value‑laden (Ward, 2026). Values shape which evaluations are commissioned, how they are designed, what outcomes get measured and ignored, and how findings are used. But I wonder whether the scarcity of explicit evaluative judgements in evaluation reports can be explained by taking seriously the reality of policymaking, and who uses or could potentially use the findings from an evaluation.
One way to understand this reality is to look at how policy actually gets made. For example, Sabatier (1988) argues that, rather than sitting neatly within a single department, most policymaking depends on shifting coalitions of actors. Adapting his argument for the UK context, this would include ministers and civil servants, opposition parties, local authorities (both elected members and officers), regulators, professional bodies, charities, think tanks, campaigners, academics, journalists, and service providers. Each brings their own priorities and values, and each has differing levels of power – and therefore differing influence – over how evidence is used.
Evaluations could offer more value by explicitly considering this diverse range of potential users of the findings, beyond the funder. When perusing Hansard, I’m always delighted to see an opposition MP asking when an evaluation is due to be published. Delighted, not always because I share their likely conclusions, but because it shows that evaluations are being used. I am unsure where, within the wider mix of actors described above, evaluation as a profession should position itself. Perhaps we shouldn’t be ashamed of delegating some evaluative judgements to others, provided we ensure that we supply the evidence needed to support those judgements.
Sometimes the values at stake, though left implicit in conclusions, are obvious, e.g., if an evaluation concludes that a programme reduces people’s risk of suicide. In other cases they are less so, and the policy landscape is marked by deep value clashes. Consider, for example, policies concerning asylum seekers or transgender people. Some policy options will cross a threshold that evaluators cannot ignore, leaving us ethically compelled to spell out the values – particularly the value clashes between policymakers and those most directly affected by policies.
Revised 30 March 2026
References
Elqayam, S., Thompson, V. A., Wilkinson, M. R., Evans, J. St. B. T., & Over, D. E. (2015). Deontic introduction: A theory of inference from is to ought. Journal of Experimental Psychology: Learning, Memory, and Cognition, 41, 1516–1532.
King, J., McKegg, K., Oakden, J., & Wehipeihana, N. (2013). Evaluative rubrics: a method for surfacing values and improving the credibility of evaluation. Journal of MultiDisciplinary Evaluation, 9, 11–20.
Mabry, L. (2010). Critical social theory evaluation: Slaying the dragon. New Directions for Evaluation, 127, 83–98.
Sabatier, P. A. (1988). An advocacy coalition framework of policy change and the role of policy-oriented learning therein. Policy Sciences, 21, 129–168.
Schröter, D., Becho, L. W., & Montrosse-Moorhead, B. (2026). The garden of evaluation approaches: Supporting explicit, theory-informed evaluation practice. Evaluation.
Scriven, M. (1994). Evaluation as a discipline. Studies in Educational Evaluation, 20(1), 147–166.
Ward, Z. B. (2026). What does it mean to say that science is value-laden? In K. C. Elliott & T. Richards, The Routledge Handbook of Values and Science (pp. 74–83). Routledge.
Whose values of merit or worth…?
Some helpful thoughts from Linda Mabry (2010) on value clashes in evaluative judgements – perhaps what we could call the fundamental problem of evaluative judgement, the value-based sibling of the fundamental problem of causal inference:
“Those who promote attention to the values of stakeholders beyond those of program managers or funders […] often refer optimistically to the importance of building consensus. But the diversity of stakeholder interests may be irreconcilable, and evaluation’s capacity to clarify differences may cement dissensus. Moreover, for federally funded programs, […] every taxpayer, every citizen, every resident is a remote stakeholder, introducing a diversity of social values that could overwhelm an evaluation.” (p. 84)
“[…] should decision-makers favor the evaluator’s values over those of program personnel and other stakeholders? For a critical social theory evaluator, this issue demands introspection, a willingness to interrogate one’s own conception of appropriate use of the evaluation. Theoretically at least, it is as possible for evaluators to misunderstand appropriate use as it is for clients to do so. While the client can count on lived experience of the program to guide ideas about appropriate use, he or she is invested in the personal values reflected in the program; while an external evaluator can count on fresh eyes and systematically collected data, he or she is invested in the personal values reflected in the evaluation. There being no disinterested view, notions of appropriate use always involve someone’s subjective values.” (pp. 90-91)
“[…] the evaluator cannot simply presume it appropriate for his or her conclusions or values to overrule those of decision-makers and other stakeholders. Errors of two types are possible. On one hand, clients might be well advised to exercise healthy skepticism in considering the work of a short-term outsider, one whose findings might point them toward unproductive territories. On the other hand, stakeholders pinched by evaluation results have been known to engage in blatant self-protection […].” (p. 91)
Mabry, L. (2010). Critical social theory evaluation: Slaying the dragon. New Directions for Evaluation, 127, 83–98.