Sampling or adjustment?

“When the nonresponse rate is 91%, any sample is a convenience sample.” (Emphasis original.)

“Remember: just about no sample of humans is really a probability sample or even close to a probability sample, and just about no regression model applied to humans is correct or even close to correct. So we have to worry about sampling, and we have to worry about adjustment.”

(Gelman, blog [re]post, 2015)

Theory of change

The “change” in “theory of change” is often interpreted as meaning change over time, which can be misleading. If a programme is designed to prevent an outcome from occurring (for example, a worsening of mental health), then there may be no pre-post change at all. Alternatively, any observed pre-post change may be driven by regression to the mean or by factors other than the programme under evaluation.

In a counterfactual impact evaluation, the “change” of interest is the expected or desired causal effect (or “treatment” effect). This is the difference between two potential outcomes: the outcome that would occur under exposure to the programme and the outcome that would occur under the control or comparison condition. Rather than describing outcomes in isolation, the theory should define the contrast between these two potential outcomes, for example whether the programme outcome is expected to be higher or lower than the control outcome.

Taking a logic model list, this would mean replacing the usual outcomes and impacts with causal effects on various time scales. It needs a name though. Some ideas:

  • Theory of causal effect (ToCE/TCE)
  • Theory of programme effect (ToPE/TPE)
  • Theory of causal contrast (ToCC/TCC)
  • Theory of difference (ToD/TDD)
  • Theory of expected difference (ToED/TED)

Alternatively, maybe it’s time to return to “programme theory” or just “theory”.

INSPECT-SR

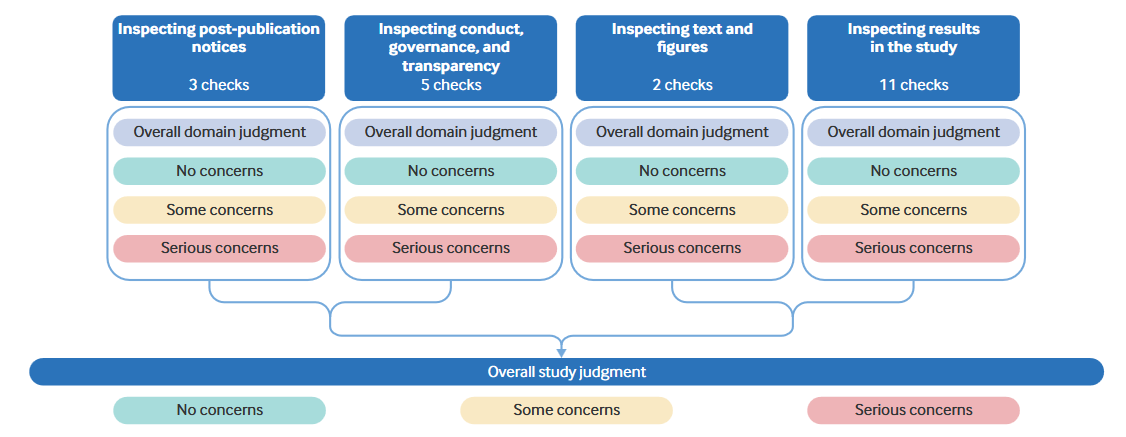
INSPECT-SR (Wilkinson et al., 2026) is a new checklist for assessing the trustworthiness of RCTs in systematic reviews. It consists of 21 items across four domains to help reviewers decide whether to include a trial in a review.

Webpage

References

Wilkinson, J., Bero, L., Heal, C., Flemyng, E., Antoniou, G. A., Aburrow, T., Alfirevic, Z., Avenell, A., Barbour, V., Berghella, V., Bishop, D. V. M., Bordewijk, E. M., Brown, N. J. L., Christopher, J., Clarke, M., Dahly, D., Dennis, J., Dicker, P., Dumville, J., … Kirkham, J. J. (2026). INSPECT-SR tool for assessing trustworthiness of randomised controlled trials. BMJ, 394, e100611.

Diff-in-diffs versus baseline-adjusted regression under regression to the mean

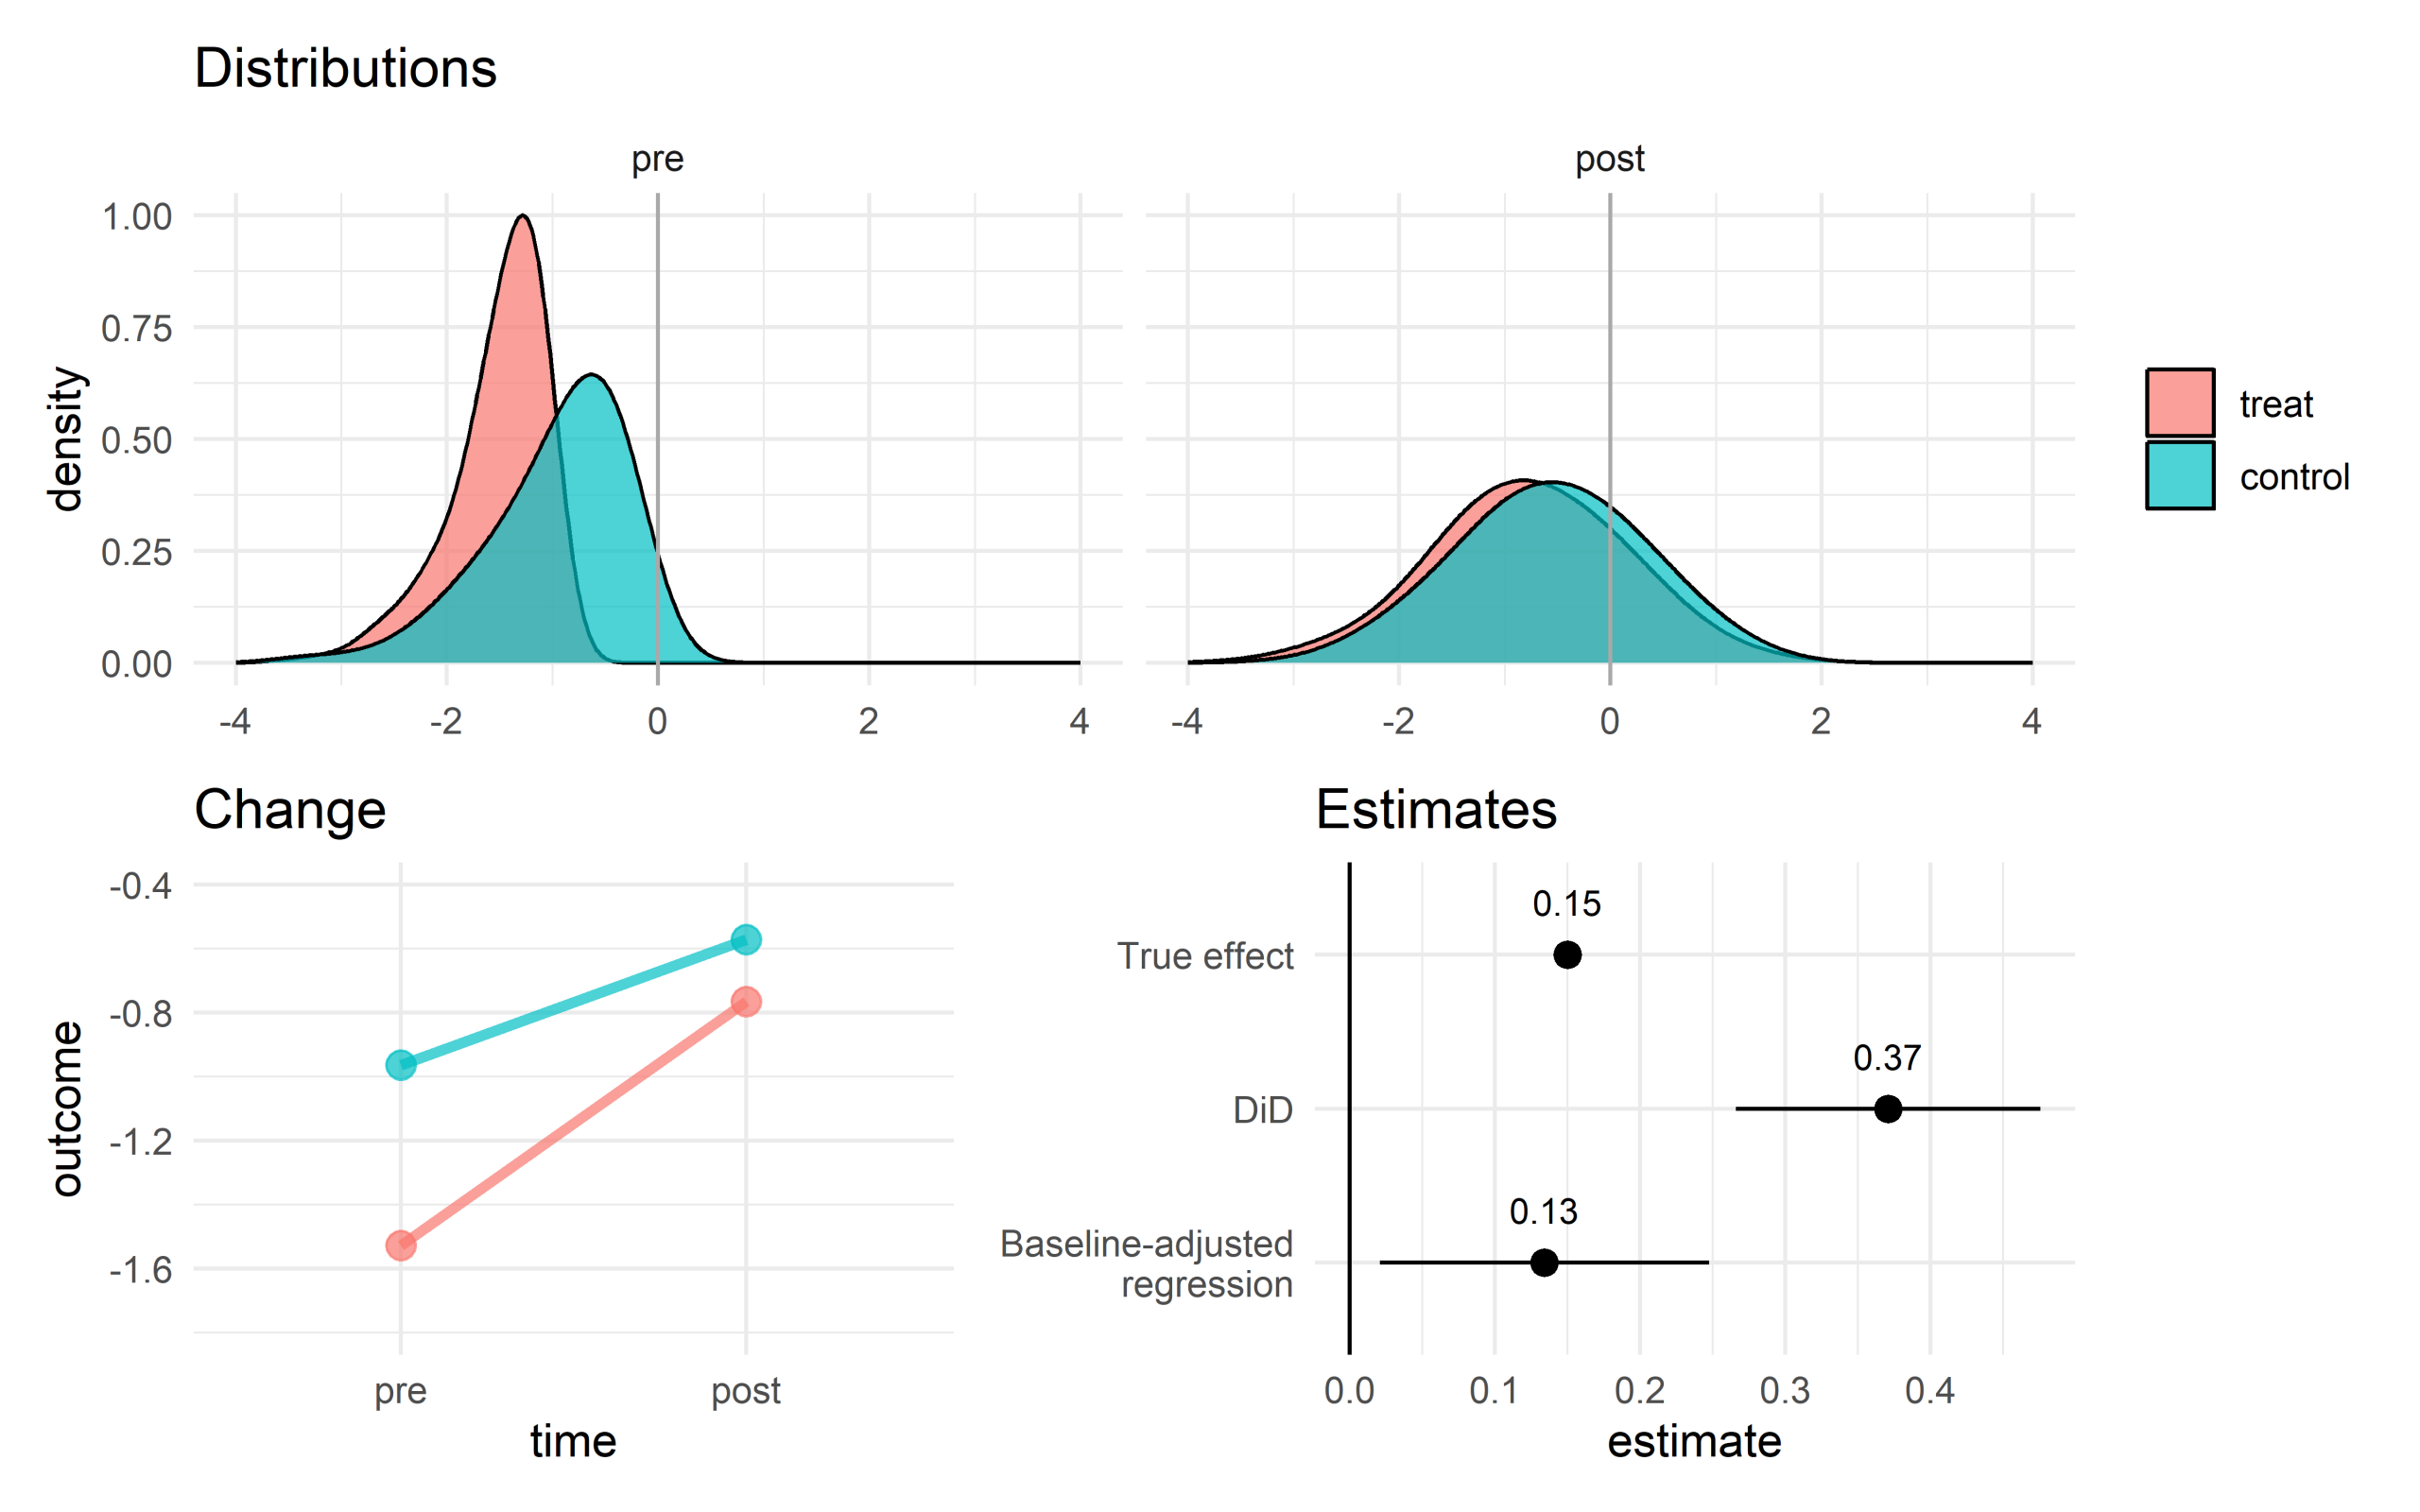
In another episode of, I wonder how well just regressing outcome on intervention group and baseline will do…? Here’s a scenario which breaks the diff-in-diffs parallel trends assumption using regression to the mean.

The treatment group observations were selected so they’re further below the mean at baseline than the control group observations, so by regression to the mean alone, the treat group will show more change. (Pre-post correlation 0.6 in the population, before selection.)

The DiD model was the usual 2×2 approach with participant fixed effects, which control for time-invariant effects that will not save us here.

The baseline-adjusted model regresses outcome on group and baseline.

The only confounder is baseline.

See Ryan (2018) for discussion of some of the muddles in the DiD lit on these kinds of effects.

References

Ryan, A. M. (2018). Well‐Balanced or too Matchy–Matchy? The Controversy over Matching in Difference‐in‐Differences. Health Services Research, 53(6), 4106–4110.

Trying elastic net regularisation with correlated predictors

First simulate data where \(x_1\) to \(x_3\) are identical and \(x_4\) is uncorrelated with them. Each \(x\) is a z-score.

Set \(y = 0.2 (x_1 + x_2 + x_3) + 0.3 x_4 + \epsilon\).

Now try elastic nets, varying \(\alpha\) from 0 (ridge regression) to 1 (lasso). I used 10‑fold cross‑validation to select \(\lambda\), keeping the coefficients for the smallest \(\lambda\), and used the same fold assignments across all values of \(\alpha\).

Here’s a picture of the coefficients. Note how the correlated predictor slopes separate as \(\alpha\) increases until only one survives with a slope of about three times 0.2 (to compensate for the other missing identical predictors). The uncorrelated predictor slope stays the same.

Here’s a table of coefficients for a selection of \(\alpha\), including the results from an unpenalised regression with only \(x_1\) and \(x_4\) as predictors:

Variableα = 0α = 0.9α = 1Unpenalised
regression
(Intercept)0.0020.0020.0020.002
x10.1980.2430.6000.603
x20.1960.188
x30.1950.169
x40.2710.2870.2870.290

Testing 1 2 3 (4 5 6 7 8 …)

When should you adjust p‑values or confidence intervals for multiple testing? It’s a complicated (and often painful) question, with the wide continuum of possible answers depicted below by Susan Ahmed (1991):

I haven’t met anyone who’s an ultra conservative (on this dimension), but it may be an interesting exercise to estimate how many statistical tests you’re likely to use in a lifetime and what, e.g., a lifetime Bonferroni penality would do to your career.

Sabine Hoffmann and colleagues (2026) offer a helpful guide on what to do. They summarise their principle as follows: “multiple testing should be adjusted for if and only if authors, when reporting and interpreting their findings, put more emphasis on the results of one or several of the tests because of their small p‑value(s)” (p. 3).

This criterion of emphasis applies throughout your reporting, from the title and abstract through to the depths of the results section and discussion. They illustrate this using the example of a study that tested the impact of seven vitamins on mortality (p. 8).

Suppose you find two statistically significant findings out of seven.

If your title were “Vitamin D and vitamin B12 are independent risk factors for all‑cause mortality”, then you need to adjust.

If your title were “Two out of seven vitamins are independent risk factors for all‑cause mortality”, then you don’t.

References

Ahmed, S. W. (1991). Issues arising in the application of Bonferroni procedures in federal surveys. ASA Proceedings of the Survey Research Methods Section, 344–349.

Hoffmann, S., Lemster, S., Collins, G., Hapfelmeier, A., Heinze, G., Mayr, A., Schmid, M., Wilcke, J. C., & Boulesteix, A. (2026). When to Adjust for Multiple Testing: A Unifying Guiding Principle. Biometrical Journal, 68(4), e70148.

Whom and context again

I reread Mayne’s (2019) on contribution analysis today and see he also allows a “what works for whom”:

“… a more interesting and important contribution claim is around this evaluation question: How and why has the intervention (or component) made a difference, or not, and for whom?” (p. 174-5).

He also allows ToCs to describe contexts: “Using nested ToCs to unpack a complex intervention and its context has worked well in numerous situations…” (p. 178).

Mayne (2012) put context in the ToCs too: “External factors – context and rival explanations – influencing the intervention are assessed and are either shown not to have made a significant contribution or, if they did, their relative contribution is recognized.” (p. 273)

So there’s another theory-based brand with a “what works for whom in what context”, plus it uses generative causation 🙃

Of course I jest. Any approach can use generative causation, whether RCT or qualitative impact evaluation. Any approach can explore moderators of impact.

References

Mayne, J. (2012). Contribution analysis: Coming of age? Evaluation, 18(3), 270–280.

Mayne, J. (2019). Revisiting contribution analysis. Canadian Journal of Program Evaluation, 34(2), 171–191.

Extended two-way fixed effects

selectTWFE looks interesting: “Estimates both a vanilla two-way fixed effects (TWFE) model and an extended TWFE (ETWFE) model, then selects between them using Cochran’s Q test for heterogeneity. When ETWFE wins, reports the heterogeneity fraction (I-squared) and cohort-time estimates with empirical Bayes shrinkage and Bonferroni multiplicity correction.”

Dismantling evaluation brands

Thomas Aston (2026) has written a really interesting discussion of debates about what counts as realist evaluation and whether it is a unique kind of evaluation.

As I’ve written before (and Aston cites), I think theorising contexts, mechanisms, and outcomes (CMOs) is important, as is recognising a gap between theory, phenomena, and evidence. However, as Pawson (2024, p. 42) notes: “All [!] scientific investigation utilises explanations relating mechanisms and contexts to empirical patterns.” It’s science-as-usual. Pawson and Tilley know this – they acknowledge and cite earlier work. For example Pawson and Tilley (1997, p. 10) cite Palmer (1975, p. 150):

“Rather than ask, ‘What works for offenders as a whole?’ we must increasingly ask ‘Which methods work best for which types of offenders, and under what conditions or in what types of setting?'”

The link with science-as-usual is clear in Pawson and Tilley (2001, p. 324):

“We have argued that good evaluation is good social science. For us, this embraces the gallant aims of precision in articulation of theory, rigor in empirical testing, confederation in lines of inquiry, and cumulation in the body of findings. The ‘realist movement,’ of which we are a part, is often considered the brash upstart of the evaluation schools. In fact, it depends on these rather venerable ideas. The future, for us, thus lies in keeping faith with some of the grand old principles of social science and in not forgetting the hard-won lessons of the old studies.”

Evaluation method(ology) debates remind me of debates about psychological therapy brands, like CBT, psychodynamic, or humanistic approaches. Mick Power (2010) is an example therapist-academic who had a go at dismantling the brands, and pulled out graded exposure, transference, and challenging dysfunctional assumptions as example techniques that are used across a range of approaches. Others have done similar, e.g., the behavioural change technique taxonomy (Michie et al., 2013) extracts a long menu of approaches that can be combined to develop a programme.

I think evaluation would make faster progress if we routinely dismantled the big evaluation brands and asked of an apparently new and unique approach:

  1. Is it really unique?
  2. Who else has done similar?
  3. What is the approach an instance of?
  4. How could the approach be used in another type of evaluation?
  5. How could a technique be combined with another?

Westhorp and Feeny (2024) used this style of reasoning for realist evaluation, and showed how regression models with interaction terms can be used to test CMOs. Baumgartner and Falk (2023) explore regression-based alternatives to the Quine-McCluskey logical minimisation algorithm used in qualitative comparative analysis (QCA), closing the gap between QCA and statistics.

When it comes to questions of metaphysics, ask: what other approaches make the same or similar assumptions, e.g., concerning ontology and epistemology? For example, there’s a trace of the gap between mechanism and measure in questionnaire design: “operationalisation”, the process of developing a measure of, e.g., a psychological construct. This process begins with the premise that the phenomena are not directly observable. It’s psychometrics 101.

And this critical dismantling strategy applies to quantitative impact evaluation approaches too. Consider “synthetic controls” developed using the synthetic control method. They sounds unique and special; however, peek behind the curtain and they’re weighted averages, with weights estimated by balancing pre-intervention measurements of the outcome and covariates. So perhaps a comparison group developed using inverse probability of treatment weighting is also a “synthetic control”…? Maybe a t-test uses synthetic treatment and control groups, with unit weights…? Or consider entropy balancing, which, when targeting the ATT, is equivalent to inverse probability tilting (IPT; Słoczyński et al., 2025). The only difference is that entropy‑balancing weights sum to the comparison‑group sample size, whereas IPT weights sum to the intervention‑group sample size.

Build bridges between the methods and methodologies and they take up less space in your brain, making it easier to design robust evaluations and communicate clearly what you’re really setting out to do.

References

Aston, T. (2026). Evaluation blogs, podcasts, and webinars in the second half of 2025: Roundup review V. Evaluation.

Baumgartner, M., & Falk, C. (2023). Configurational Causal Modeling and Logic Regression. Multivariate Behavioral Research, 58(2), 292–310.

Michie, S., Richardson, M., Johnston, M., Abraham, C., Francis, J., Hardeman, W., Eccles, M. P., Cane, J., & Wood, C. E. (2013). The Behavior Change Technique Taxonomy (v1) of 93 Hierarchically Clustered Techniques: Building an International Consensus for the Reporting of Behavior Change Interventions. Annals of Behavioral Medicine, 46, 81–95.

Palmer, T. (1975). Martinson Revisited. Journal of Research in Crime and Delinquency, 12(2), 133–152.

Power, M. J. (2010). Emotion focussed cognitive therapy. John Wiley & Sons.

Słoczyński, T., Uysal, S. D., & Wooldridge, J. M. (2025). Covariate Balancing and the Equivalence of Weighting and Doubly Robust Estimators of Average Treatment Effects. IZA Institute of Labour Economics Discussion Paper, 18147.

Westhorp, G., & Feeny, S. (2025). Using surveys in realist evaluation. Evaluation Journal of Australasia, 25(1), 45–64.
Quasi-experiment sample size

Two papers caught my attention on sample‑size calculation: one for difference‑in‑differences designs (Hedberg & Hedges, 2026) and another for propensity score weighted designs (Liu et al., 2026).

Difference-in-differences (DiD)

Hedberg and Hedges (2026) have developed a method for estimating minimum detectable effect size (MDES) for DiD, including R code in an appendix. The approach takes account of variance explained by covariates (which could include fixed effects for units) and covariate imbalance. It also allows for unequal sample sizes. To run in reverse and estimate sample sizes, there’s a multitude of ways to get R to search across a range of sample sizes and minimise the difference between the achieved and target MDES.

Some things to bear in mind:

It handles both repeated cross-sectional and mixed between-within designs; for the latter, use fixed effects (so \(n-1\) covariates for \(n\) units) alongside an estimate of the variance explained. The parameters include the number of observations, not participants. So for a 2×2 design with pre and post measures from each participant, you will need to multiply the number of participants by 2.

There’s an error in the published code:

if (rho1 > 1) {
  V <- V*(1/(1-rho1^2))
}
if (rho2 > 1) {
  V <- V*(1-rho2^2)
}

Those rhos should never be over 1, and earlier checks won’t allow them to be. The code should check if they are over zero:

if (rho1 > 0) {
  V <- V*(1/(1-rho1^2))
}
if (rho2 > 0) {
  V <- V*(1-rho2^2)
}

I spotted this during testing: increasing the variance explained by covariates did not affect the MDES, and the results differed from the simulation checks. The corrected version resolves this, and the authors very kindly and promptly confirmed the fix. I understand that updated code will be available on the journal’s website soon. In the meantime, the edits noted above should address the issue.

Propensity score weighting

I had been using Austin’s (2021) work to approximate VIFs from c-statistics of propensity score models, which represent lack of overlap in propensity score distributions between groups. The resulting VIFs can then be used to inflate sample sizes estimated from standard power calculators.

Liu, Yang, and Li (2026) have developed an alternative approach that does the sample size estimation in one go, depending on prevalence of the intervention, and an overlap parameter, \(\phi\), which is 1 with perfect overlap and decreases as the propensity score distributions separate. The approach has been implemented in the R package PSpower, which is on CRAN.

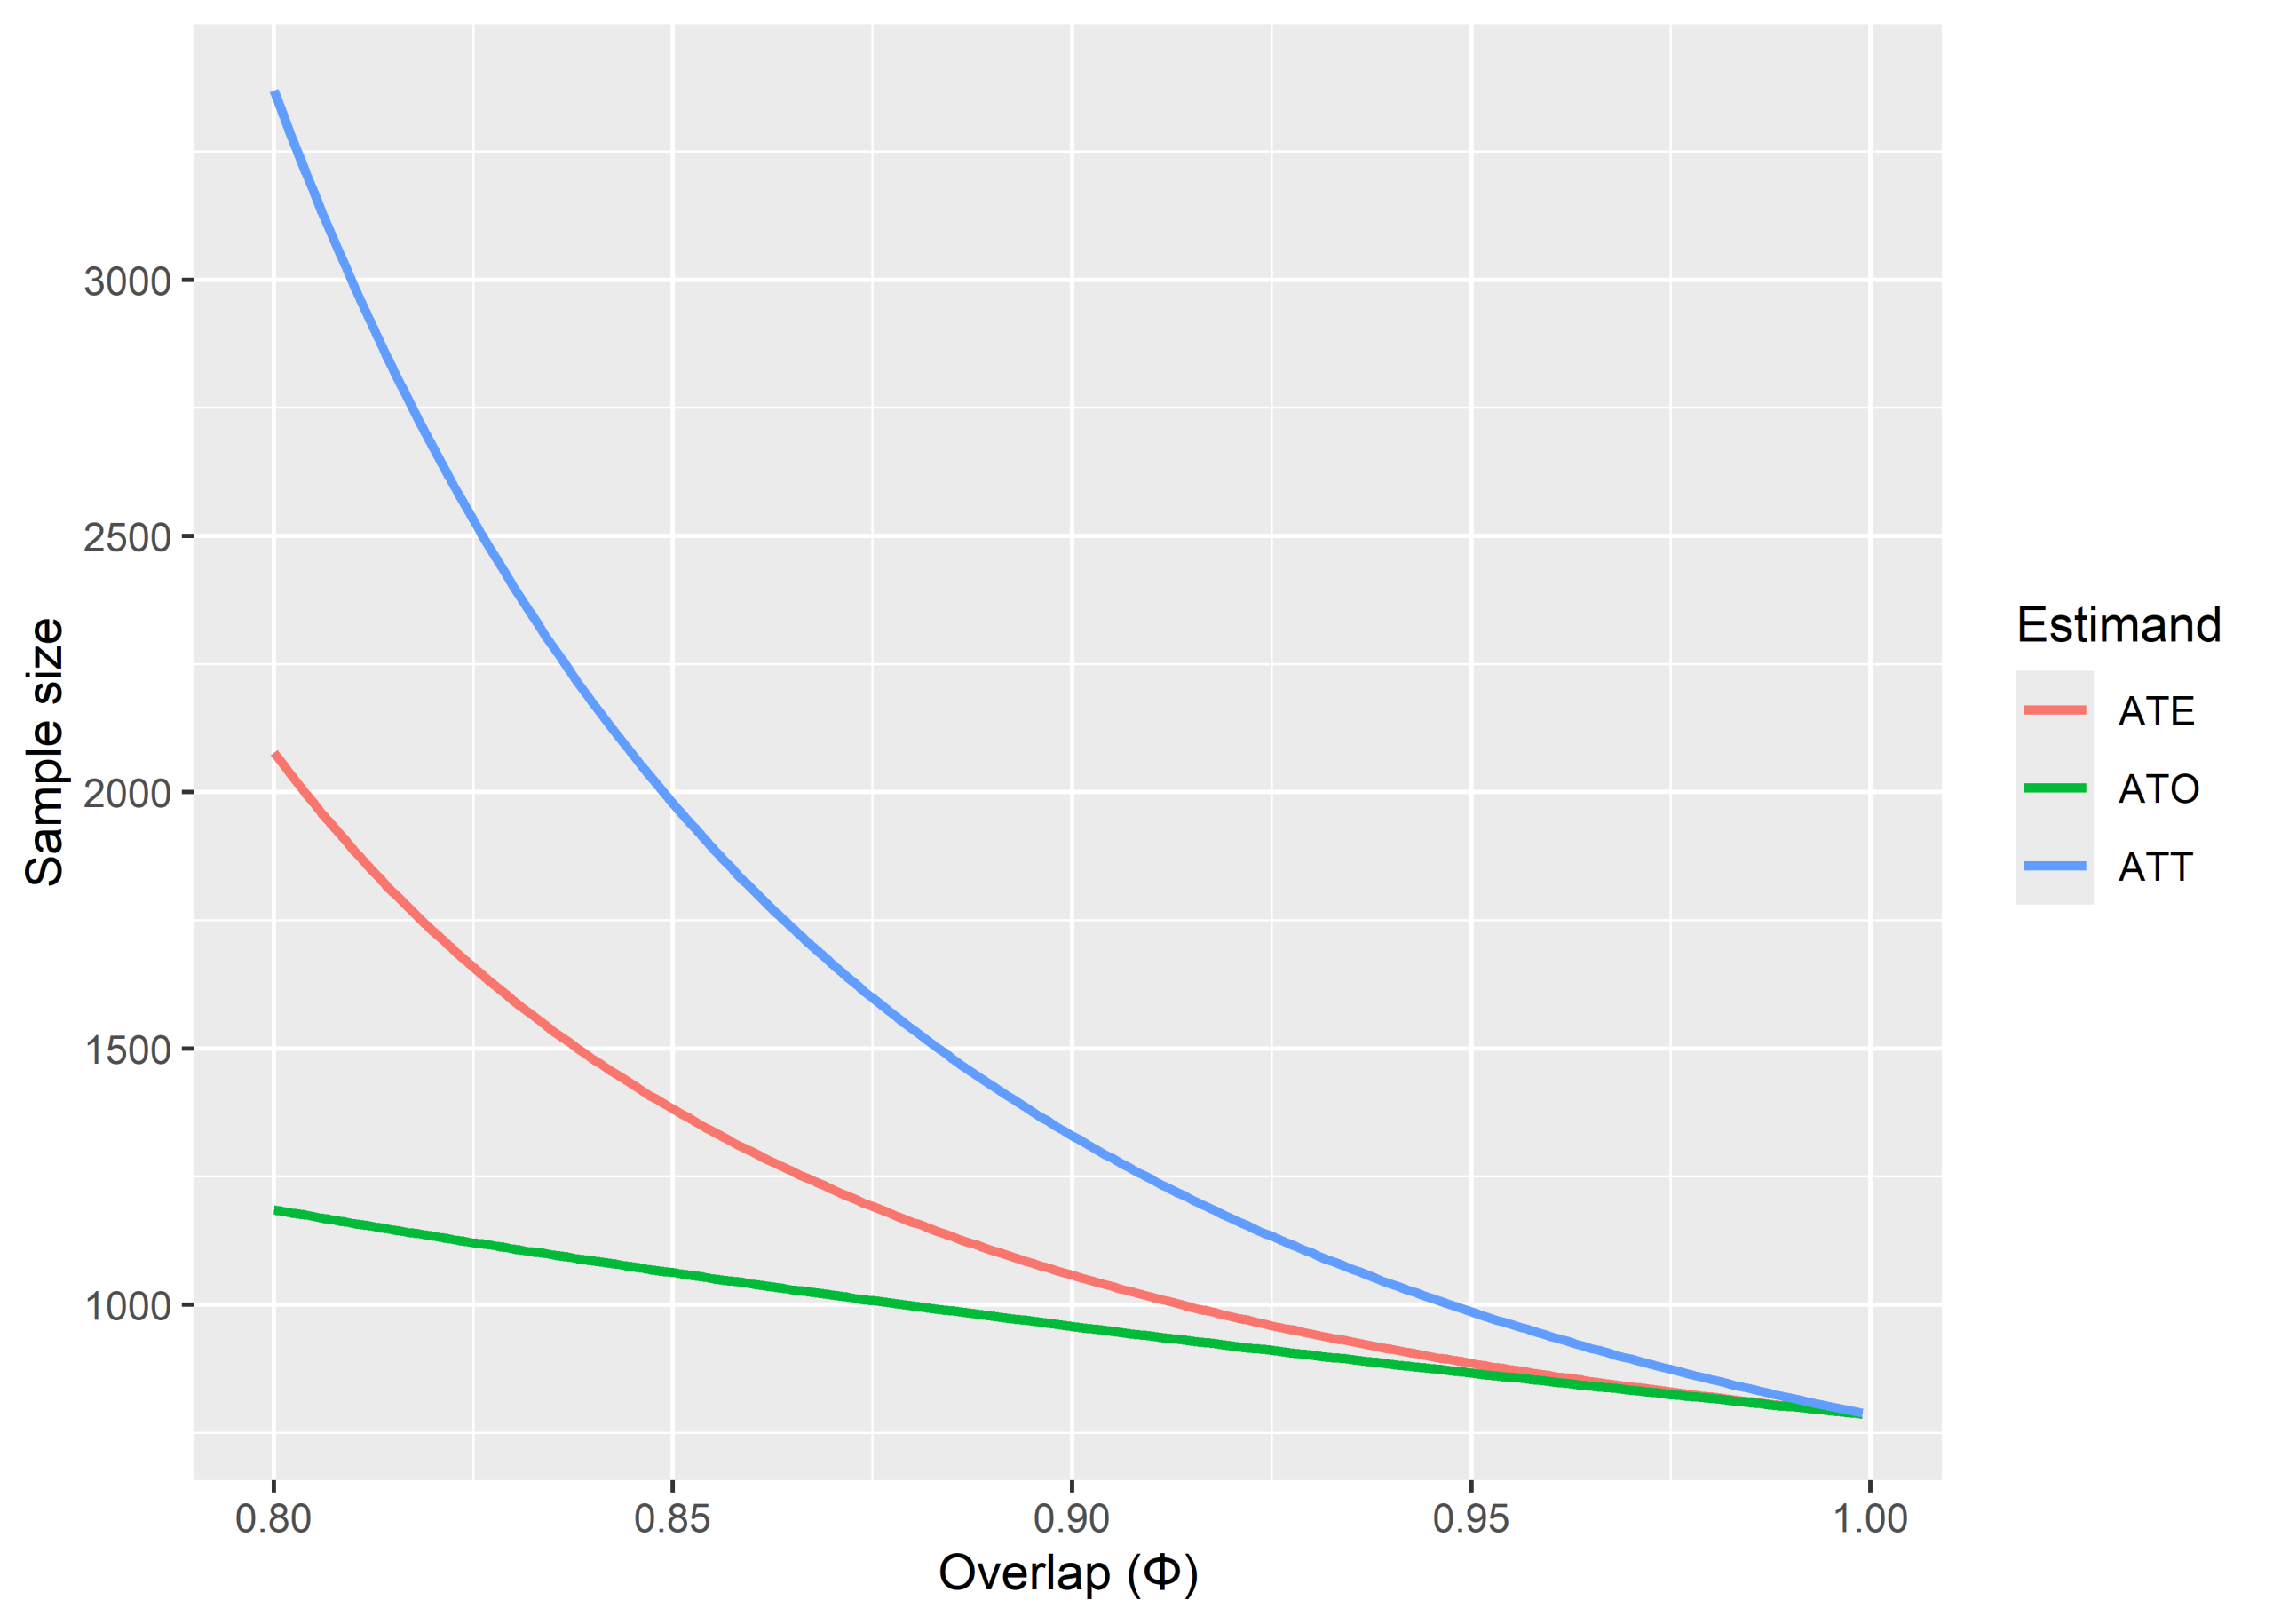
It’s speedy. Here’s an example with intervention prevalence at 50%, MDES 0.2, and varying the overlap from 80% to 99%, for the ATE, ATT, and ATO estimands. ATO is least affected by lack of overlap because it deliberately defines the estimand on the region where there is most overlap and down-weights observations that are far from there. ATO has a policy interpretation too: impact for people in the region of decisional equipoise.

References

Austin, P. C. (2021). Informing power and sample size calculations when using inverse probability of treatment weighting using the propensity score. Statistics in Medicine, 2, 1–14.

Liu, B., Yang, C., & Li, F. (2026). Sample size and power calculations for causal inference of observational studies (Version 5). arXiv, to appear in Annals of Statistics.

Hedberg, E. C., & Hedges, L. V. (2026). Computing Statistical Power for the Difference in Differences Design. Evaluation Review, 50(1), 149–180.