Blog 🎤

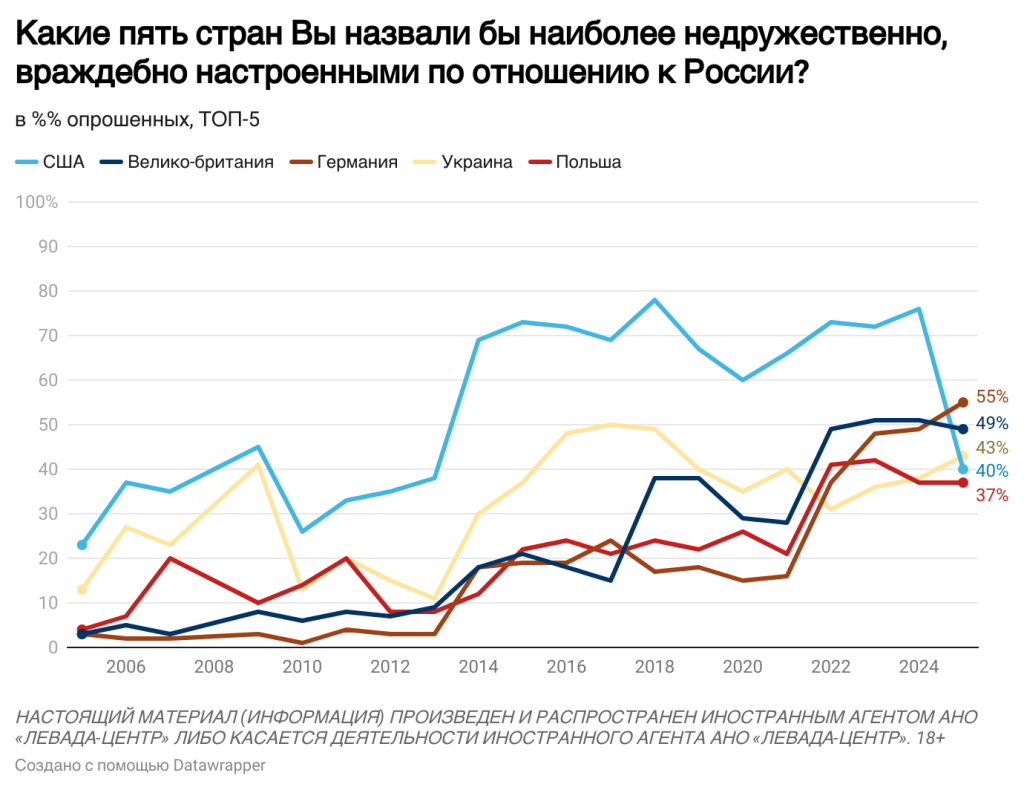
Most Russians no longer view the US as Russia’s main enemy (Levada poll, 5 June 2025)

Levada’s latest poll finds that 40% of Russians view the US (США) as most hostile towards it, nearly half the percentage who held that view in 2024 before Trump was elected (76%). The UK (Велико-британия) is viewed as most hostile by 49%, Germany (Германия) by 55%, and Ukraine (Украина) by 43%. Poland (Польша) is also in the top 5, at 37%.

Original data

Moscow Times Report

PsychoModels

“PsychoModels’ mission is to expand and improve mathematical and computational modeling practices across psychological science. Computational modeling is increasingly relevant for psychological research, but traditional publication outlets don’t facilitate its usefulness. Major issues are the lack of documentation standards, indexing systems, or systematic links between repositories. PsychoModels creates a curated resource addressing these issues. The aim is a comprehensive inventory of mathematical and computational models, connecting publication records with entries in code and data repositories, enriched by markers of psychological context, that can be easily accessed and queried. Finally, PsychoModels intends to facilitate the development of a common language around modeling; communication between researchers; model review efforts; reuse of the models in the database; and the improvement of modeling education in all areas of psychology.”

van Dongen, N.N.N., & Volz, L. (2024). PsychoModels: The mathematical and computational model repository for psychological science. https://psychomodels.org

Government Evaluation Conference 2025 – two quick thoughts

It was a privilege to attend the Government Evaluation Conference this week. One new mantra for me is going to be, ensure evaluations are robust and proportionate. An evaluation should be rigorous enough to learn about programmes and policies, and to rule out alternative explanations for change, but it shouldn’t place excessive burdens on service users or programme delivery teams.

A practical way to ensure proportionality is to be disciplined with evaluation questions. Each additional question increases the burden for everyone involved and raises the likelihood that answers will be superficial or inaccurate. The critical questions to ask are: What do you really (really) need to know, and how will the answers be used?

There were also interesting discussions about (what are currently being called) “test and learn” approaches, which reminded me of continuous quality improvement (CQI) – something that is (or at least was) widely practised in healthcare. The idea is to identify aspects of service delivery that can be implemented quickly, measured easily, and that are known (from previous evaluations) to contribute to important impacts downstream. However, while such rapid implementation and feedback loops can be helpful, there will always be a need for longer-term follow-up with large samples to confirm that change has scaled and that desired impacts are actually being achieved.

ITT ATT

Intention to treat (ITT) analyses code a participant’s group according to the condition they were assigned to, regardless of whether they engaged with that condition or, e.g., swapped to another. Sometimes the average treatment effect on the treated (ATT) estimand is misunderstood to mean analysing people according to what intervention they actually engaged with. But the two concepts are independent of each other and depend on how the potential outcomes are defined.

For example, let Yᵢ(ai) denote the potential outcome for participant, i, were they to be assigned to the intervention, and Yᵢ(ac) denote the potential outcome were they to be assigned to some comparison condition. Let Gᵢ denote the group they were assigned to (note, not necessarily what they engaged with!). The following estimand is an ITT ATT:

E[Yᵢ(ai) – Yᵢ(ac) | Gᵢ = ai]

Intervals for individuals

A clear and concise guide to choosing between the standard error of measurement (SEM) interval and the standard error of estimation (SEE) interval – two intervals that are used when interpreting an individual’s score in psychological testing (Schmukle and Rohrer, 2025).

Some areas, such as the personality test industry, would benefit from more often using any kind of interval on their proclamations.

Schmukle, S. C., & Rohrer, J. M. (2025). Clarifying the Choice of Confidence Intervals in Psychological Testing: A Comment on Stanley and Spence (2024). Advances in Methods and Practices in Psychological Science.

Key study design considerations in state policy evaluation

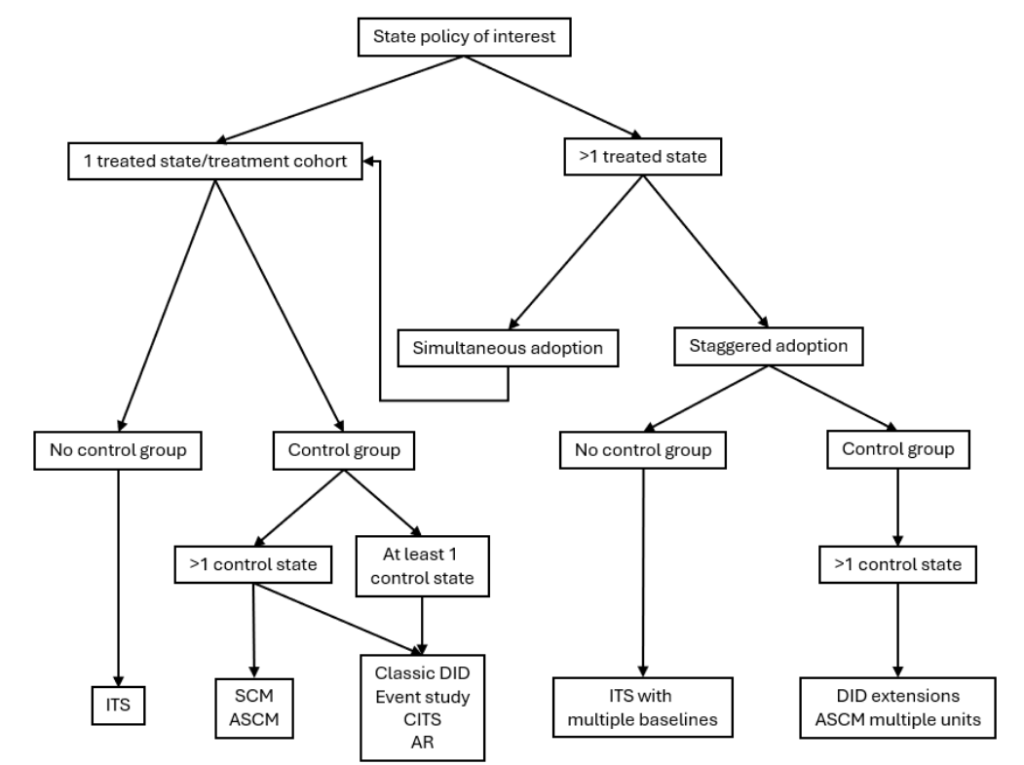
A new preprint by Elizabeth Stone and colleagues explores methods for evaluating state-level policies in the US, offering insights relevant to UK policy evaluation. It covers selection of a range of approaches based on, for example, how a policy varies across the country, whether there is staggered roll out, and the availability of baseline data.

References

Stone, E. M., Schuler, M. S., Stuart, E. A., Rubinstein, M., Griswold, M., Stein, B. D., & Griffin, B. A. (2025). Choosing an analytic approach: Key study design considerations in state policy evaluation.

Hearing impairment and incident heart failure

Another potential example for a DAG or two. Huang et al. (2025) found an association between hearing impairment and subsequent heart failure, which they attributed to a common cause of systemic vascular disorders. I don’t know anything about either topic, but it sounds plausible – more so than, e.g., hearing loss causing heart failure. They also found that whether people wore a hearing aid did not moderate this association – which again makes sense, though it was unclear what the authors expected:

“Of note, both the participants who used hearing aids and those with poor hearing status had a similarly significant increase in the risk of incident HF, suggesting that while hearing aids can improve auditory function, they may not address the underlying vascular issues that contribute to the risk of HF.”

I think it’s missing an “unsurprisingly”, but again don’t know the topic.

But then the mediation test comes along and suggests that the association between hearing loss and heart failure is mediated by psychological factors such as stress. Now how to get that in a DAG with the common cause model.

Here’s the relevant paragraph:

“Second, we found that the positive association between poor hearing status and incident HF was significantly mediated by psychological factors. Because hearing problems can lead to difficulties in speech comprehension and poor engagement in social activities, people with hearing impairment are more likely to experience social isolation, psychological distress, anxiety and depression than people without hearing impairment. These psychological factors may increase the activity of the sympathetic nervous system and the hypothalamic-pituitary-adrenal axis, and enhance inflammation and oxidative stress, thereby accelerating atherosclerosis, increasing peripheral stress, and promoting the development of cardiac remodelling in the pre-HF period, thus significantly increasing the risk of HF.”

References

Huang, Y., Zhang, Y., Zhang, Y., Xiang, H., Ye, Z., Yang, S., Gan, X., Wu, Y., Zhang, Y., & Qin, X. (2025). Hearing impairment, psychological distress, and incident heart failure: A prospective cohort study. Heart, heartjnl-2024-325394.

RCTs can and do use sensible control groups

If there are effective treatments for a condition, then a placebo-controlled randomised trial would generally be unethical (see below for exceptions discussed in the literature). But RCTs do not need to use placebo control.

There is a common misconception that an RCT should have a “pure” control (whatever that means) and if an active control of some description is used, e.g., another treatment, then it becomes A/B testing. This is false. A/B testing is just a type of trial and the term is more commonly used in marketing, e.g., in studies of variations of a website design.

RCTs can and do have active controls. Education trials and psychological therapy trials often use usual practice controls. Once effective Covid vaccines had been found, trials investigated the comparative efficacy and safety of different vaccines.

Example discussions

“Often, trials are conducted to compare a new intervention against current practice. The new intervention might be a small change, or a set of small changes to current practice; or it could be a whole new approach which is proving to be successful in a different country or context, or that has sound theoretical backing.” (Haynes, Goldacre, & Torgerson, 2012, p. 20)

“An RCT is not necessarily a test between doing something and doing nothing. Many interventions might be expected to do better than nothing at all. Instead, trials can be used to establish which of a number of policy intervention options is best.” (Haynes, Goldacre, & Torgerson, 2012, p. 21)

“Placebo controls are clearly inappropriate for conditions in which delay or omission of available treatments would increase mortality or irreversible morbidity in the population to be studied. For conditions in which forgoing therapy imposes no important risk, however, the participation of patients in placebo-controlled trials seems appropriate and ethical, as long as patients are fully informed.” (Temple & Ellenberg, 2000, p. 460)

“In cases where an available treatment is known to prevent serious harm, such as death or irreversible morbidity in the study population, it is generally inappropriate to use a placebo control. There are occasional exceptions, however, such as cases in which standard therapy has toxicity so severe that many patients have refused to receive it.” (European Medicines Agency, 2001, p. 16)

“Many placebo-controlled trials are conducted as add-on trials, where all patients receive a specified standard therapy or therapy left to the choice of the treating physician or institution.” (European Medicines Agency, 2001, p. 16)

References

European Medicines Agency (2001). ICH Topic E 10: Choice of Control Group in Clinical Trials.

Haynes, L., Goldacre, B., & Torgerson, D. (2012). Test, learn, adapt: developing public policy with randomised controlled trials. Cabinet Office and Behavioural Insights Team.

Temple, R., & Ellenberg, S. S. (2000). Placebo-controlled trials and active-control trials in the evaluation of new treatments. Part 1: ethical and scientific issues. Annals of Internal Medicine, 133(6), 455-463.
Evaluation Registry

The Evaluation Registry is a service owned by the Cabinet Office and HM Treasury Evaluation Task Force (opens in new tab).

This is where planned, ongoing and complete government evaluations from all departments and the Scottish Government are registered.

Search here.

Green Book review

Debated 2 April 2025 Westminster Hall. Hansard link.

Sarah Russell (Lab): “We believe that the review must be done with ambition and a willingness to challenge underlying customs and practices. In particular, it needs to learn from the successes and failures—largely failures, I would say—of previous Green Book reviews, in particular the 2020 review.”

“There is a consultancy industry around the Green Book, and that raises the cost of developing a successful business case. It also makes it very difficult for smaller local authorities to successfully put together a business case because the complexity of doing so is absolutely mind boggling. Frankly, the whole thing is just a bunch of piffle—we need to make this very simple and outcomes driven.”

Jeevun Sandher (Lab): “For too long, investment has been biased towards London and the south-east. Someone living in London gets £800 more infrastructure spending per year than the national average. That is because the cost-benefit analysis set out in the Green Book to evaluate projects has a hardwired London bias. First, the Green Book prices the benefits of projects in a way that benefits places with higher wages—namely, London. Secondly, it does not estimate the wider impact of investment on growth.”

Andrew Cooper (Lab): “The Green Book is part of a colourful spectrum of current Government guidance and standards documents, which alongside the Aqua Book, the Magenta Book, the Orange Book and 19 other publications and pieces of supplementary guidance forms the basis of how the Treasury appraises policies, programmes and projects. On top of that, several Departments have issued their own interpretation of the guidance as it applies to them, thankfully avoiding extending the colourful metaphors any further.

“That complexity—well over 1,000 pages of guidance—is at the root of the criticism of the small industry and almost mysticism around navigating the assessment process and of the poor outcomes to which it leads.”

“Local authorities tell me it is still common practice for response letters to open with sentences such as, “We note that the BCR for the proposed scheme is 1.8.” That belies the intent of the 2020 review. […] The review must end the arbitrary BCR thresholds across Government.”